Category Archives: Neocloud

Why Nscale is failing

Claiming to break every record for moving fast and attaining huge amount of funding as a start-up is a huge potential to fail..

I was set-up to fail working at Nscale and now Nscale have been set-up to fail as a Neocloud…
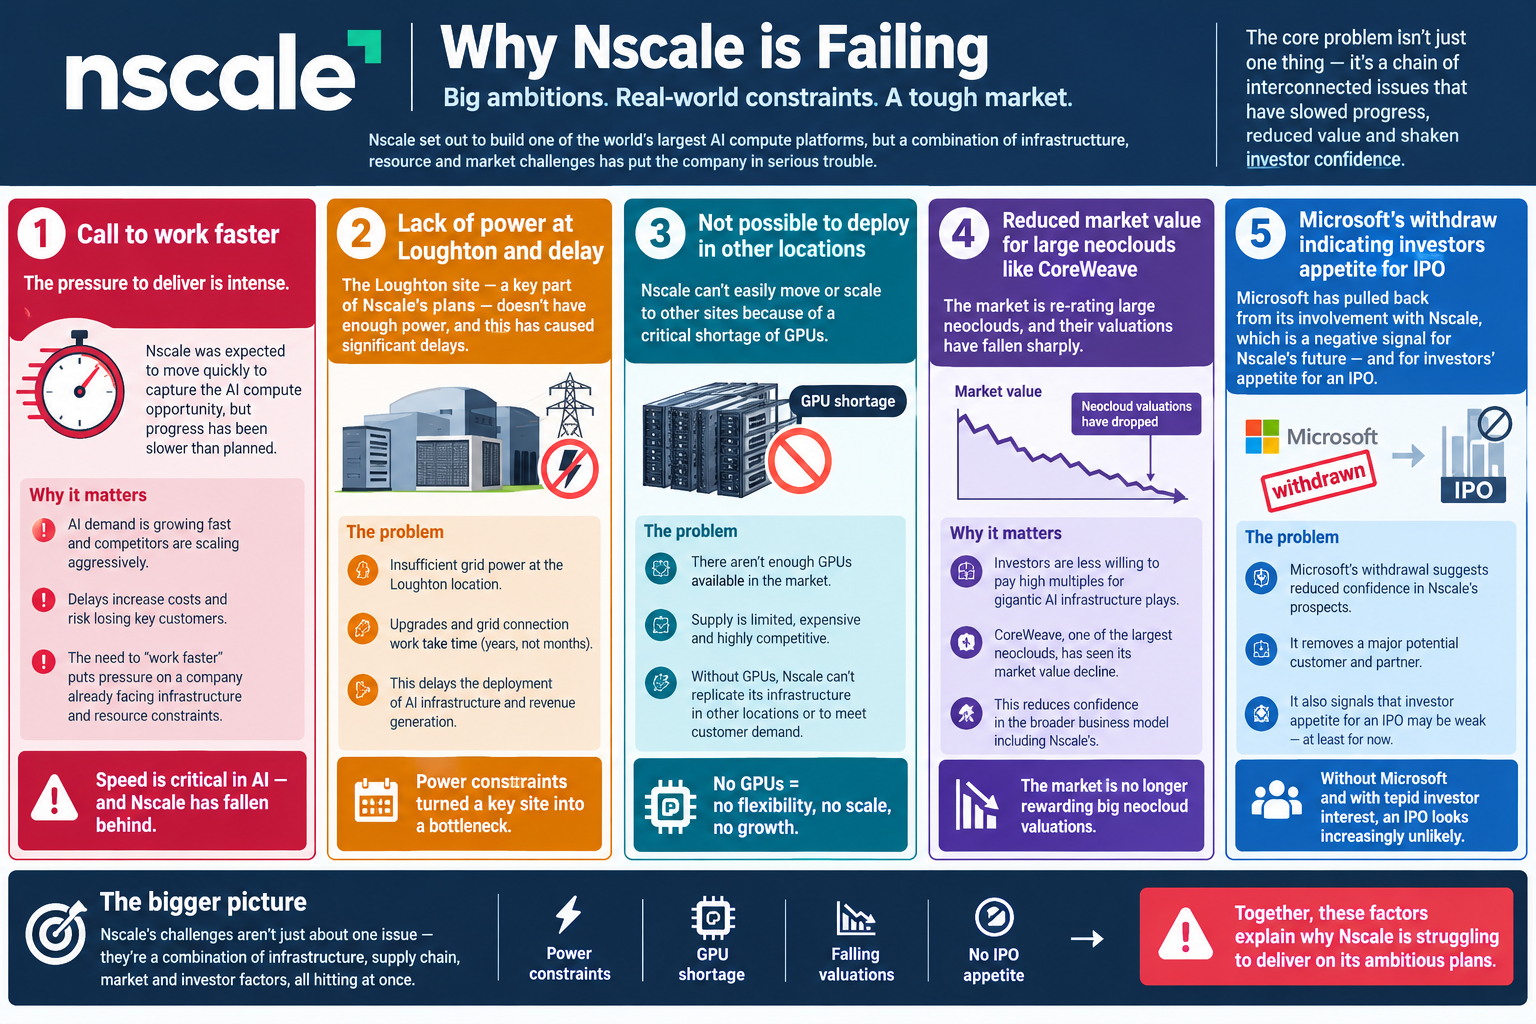
Tell me how hard it is for Nscale to satisfy request to move faster: https://news.google.com/s/CBIwtYqon-oB?sceid=GB:en&r=0&oc=1

How hard is it for Nscale to “move faster”?

My assessment: very difficult — roughly 8/10 for accelerating delivery of fully operational AI data-centre capacity. The problem is that Nscale cannot solve every delay simply by asking its engineers to work harder.

The Bloomberg report published on 22 October 2026, Nvidia’s Huang Urged Nscale to Move Faster After Early Setbacks, says Jensen Huang urged Nscale to work around the clock following setbacks involving data-centre delivery. These included delays, equipment failures and power constraints.

Bloomberg

The crucial distinction is between working faster on things Nscale controls and making infrastructure available sooner when external constraints prevent it.

1. The main obstacles

1. Electricity and grid connections

Very difficult

The Loughton, Essex, project was intended to provide 50 MW of capacity from 23,040 Nvidia GB300 GPUs. Grid connection delays pushed the expected power supply into the 2030s, prompting Microsoft to withdraw from that site’s agreement. No amount of overtime can fix a grid connection that is years away. Alternative power generation might help, but it brings engineering, planning, cost and safety challenges.

Reuters

2. Hardware deployment and commissioning

Very difficult

GPU servers, networking, power distribution, cooling and storage must all work together. Equipment failures and integration problems can block commissioning. Engineers can improve installation automation, testing and fault diagnosis, but defective equipment and supplier lead times impose hard limits.

3. Scaling the operating platform

Difficult

It is one thing to build a functioning cluster; it is another to deliver repeatable, reliable GPU capacity across multiple sites. Provisioning, network configuration, observability, capacity management, failure recovery and customer onboarding all need to scale together.

4. People, processes and coordination

Difficult

Rapid expansion increases the number of teams, suppliers, contractors and dependencies. More staff and longer hours can increase throughput, but they can also increase coordination overhead, operational mistakes and rework if the delivery process is immature.

2. Why the scale of the challenge matters

The gap between Nscale’s contracted business and its operating infrastructure is particularly important.

Reported position as of late August 2026

$103bn+

Total contracted value

$2.6bn

Value associated with active capacity

These figures are not directly comparable measures of delivered capacity: one represents contracted value over time, while the other relates to already-active capacity. Nevertheless, the difference illustrates the challenge of converting a huge pipeline of commitments into operating infrastructure.

Reuters

The Financial Times also reported that fulfilling Nscale’s future commitments would require deploying approximately 461,000 GPUs, nearly 20 times its then-current capacity. That is a major industrial-scale deployment programme, not simply a software delivery project.

Financial Times

3. What can Nscale actually accelerate?

AreaPotential to move fasterWhy
Infrastructure automationHighReduce manual deployment and configuration
Software and platform engineeringHighImprove testing, provisioning and release cycles
Fault diagnosis and recoveryHighReduce downtime and commissioning delays
Hardware procurementModerateDepends on supplier capacity and availability
Data-centre constructionModerate to lowDepends on contractors, equipment and site readiness
Electricity availabilityLow where the grid is constrainedDepends on network capacity, connections or alternative generation
End-to-end deliveryVariableDetermined by the slowest critical dependency

These are engineering assessments rather than reported measurements of Nscale’s internal performance.

The most effective approach is to identify the critical path for each site and remove its actual bottlenecks. Adding engineers to a team whose deployment process is slow can help. Adding engineers to a project waiting for electrical power cannot solve the principal problem.

4. What does Jensen Huang’s demand mean for the company?

There are three distinct interpretations.

  • A genuine execution problem: Nscale may need tighter delivery management, better commissioning procedures and more predictable deployment.
  • A mismatch between commercial ambition and physical delivery: signing large contracts is not the same as bringing the promised computing capacity online.
  • Pressure from customers and investors: delays become especially costly when customers have deadlines and investors expect rapid conversion of contracts into revenue. Reuters’ reporting on the Microsoft withdrawal illustrates the commercial consequences of a missed infrastructure deadline. Reuters+1

Huang’s instruction to work around the clock is therefore a demand for urgency, not evidence that the underlying problems can all be solved by working longer hours.

My conclusion

Nscale’s challenge is not that every part of its business is inherently slow; it is that several complex delivery processes must succeed simultaneously at enormous scale.

I would distinguish two targets:

  • Accelerating engineering and operational execution: achievable over weeks or months if there are genuine process and automation bottlenecks.
  • Accelerating the delivery of hundreds of thousands of GPUs across data centres: much harder, potentially taking years, because power, construction, procurement, commissioning and financing all interact.

The key question is whether Nscale’s delays are predominantly caused by fixable execution weaknesses or by external infrastructure constraints. If they are mostly the former, Huang’s pressure could produce substantial improvements. If they are mostly the latter, the company can improve its execution considerably and still miss some delivery dates.

The public reporting establishes that Nscale faces both types of challenge, but does not reveal enough of its internal project data to quantify their relative contribution.
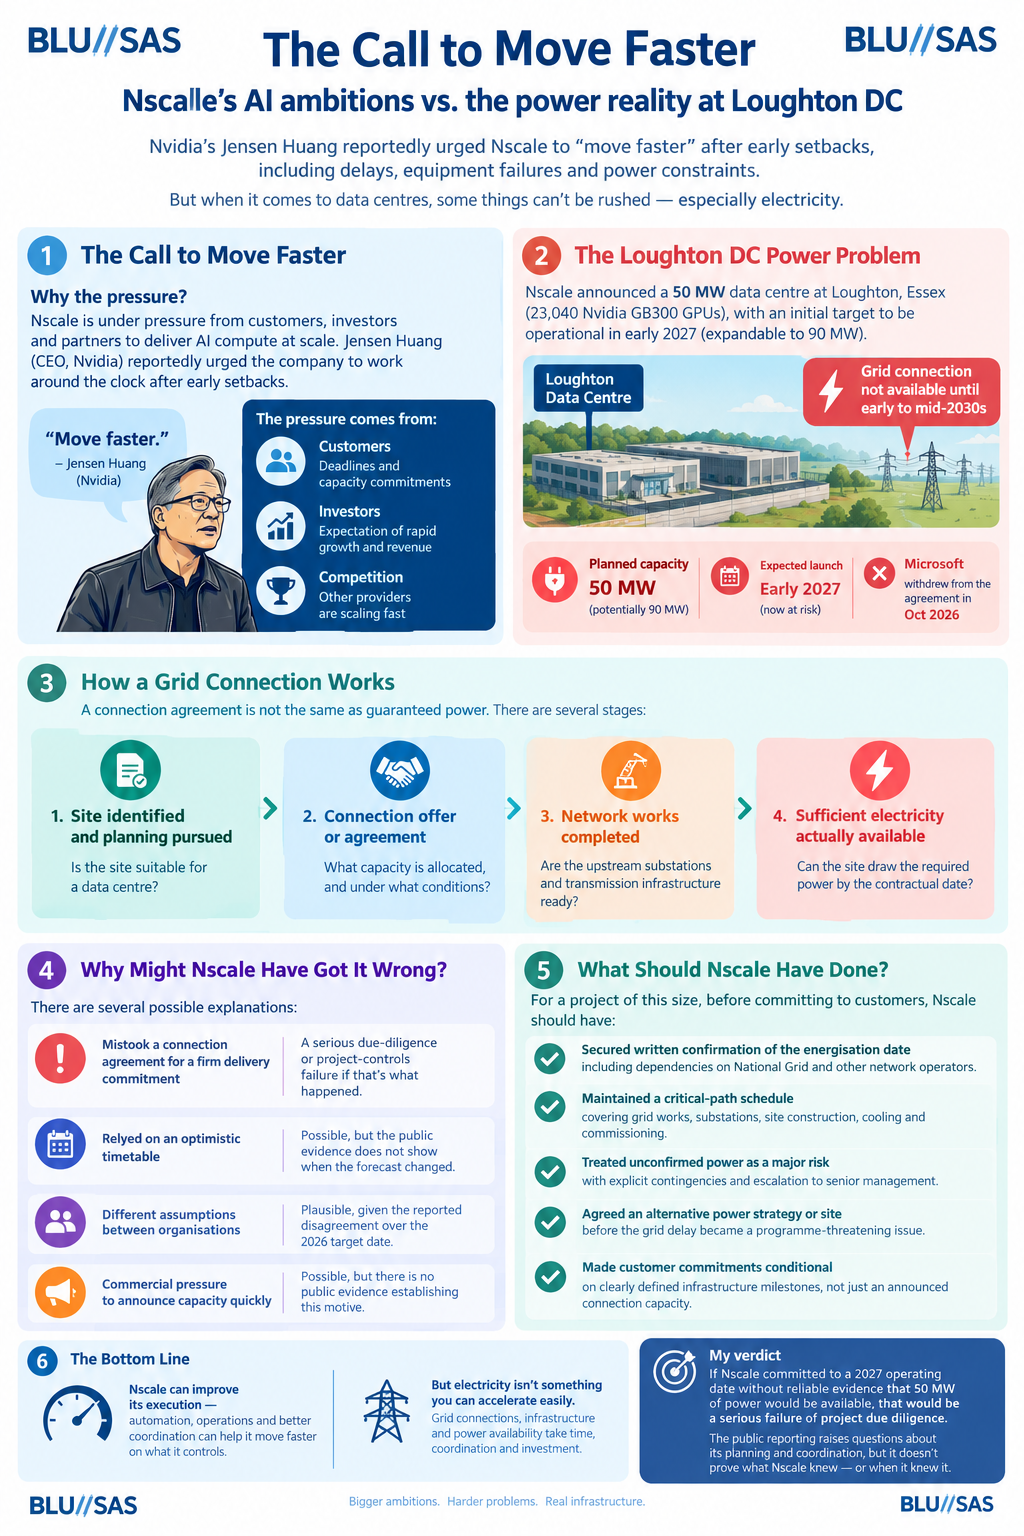
Loughton DC power issue

https://www.theguardian.com/technology/2026/sep/24/construction-largest-supercomputer-delayed

Why didn’t Nscale know about the power issues especially relating to the Houghton DC?

The short answer: Nscale may have known about the risk, but failed to secure a dependable power-delivery date.

The reporting on the Loughton data centre in Essex raises a serious question about project due diligence. However, there is an important difference between knowing that a grid connection is planned and having confirmation that sufficient electricity will actually be available by the required date.

The project was announced in 2025, with an intended opening in early 2027 and a planned initial capacity of 50 MW, potentially expanding to 90 MW. UK Power Networks subsequently indicated that sufficient grid power might not be available until the early to mid-2030s. Microsoft then withdrew from its agreement for that site in October 2026.

The Guardian

That is a potential gap of several years between the commercial delivery plan and the physical infrastructure needed to operate it.

1. The most revealing detail: Nscale reportedly had a 90 MW connection arrangement

This is where the story becomes more interesting.

According to City AM, Nscale had secured planning permission and a 90 MW grid connection arrangement, but the actual supply was expected much later than originally anticipated.

City AM

According to Data Center Dynamics, the original late-2026 completion target had been agreed with UK Power Networks, but National Grid said it had not agreed to that target date.

DCD

That points to a potentially significant misunderstanding or failure of coordination between the parties.

A grid connection is not a single yes-or-no decision. There are several stages:

1. Site identified and planning pursued

Is the site suitable for a data centre?

2. Connection offer or agreement

What capacity is allocated, and under what conditions?

3. Network works completed

Are the upstream substations and transmission infrastructure ready?

4. Sufficient electricity actually available

Can the site draw the required power by the contractual date?

A project can progress through the first two stages without the last two being ready.

One important qualification: the public reports do not establish the exact legal terms of Nscale’s connection agreement or precisely when each party learned that the timetable was unachievable.

2. So why might Nscale have got it wrong?

I see four plausible explanations.

Possible explanationMy assessment
It mistook a connection agreement for a firm delivery commitment.A serious due-diligence or project-controls failure if that is what happened.
It relied on an optimistic timetable that later deteriorated.Possible, but the public evidence does not establish when the forecast changed.
Different organisations had different assumptions about who would deliver the upstream network works.Plausible given the reported disagreement over the 2026 target date.
It accepted the risk because of commercial pressure to announce capacity quickly.Possible, particularly given the rapid expansion plans, but there is no public evidence establishing that motive.

The distinction between the first two explanations matters. A project team can make a reasonable forecast that subsequently proves wrong. It is much harder to defend committing to a customer delivery date without sufficiently robust evidence that the required power will be available.

3. What should Nscale have done?

For a project requiring 50–90 MW, I would expect the following before making a firm customer commitment:

  • Obtain written confirmation of the energisation date, including any dependencies on National Grid and other network operators.
  • Maintain a documented critical-path schedule covering grid works, substations, site construction, cooling and commissioning.
  • Treat unconfirmed power availability as a major delivery risk, with explicit contingencies and escalation to senior management.
  • Agree a credible alternative power strategy or alternative site before the grid delay becomes a programme-threatening issue.
  • Make customer commitments conditional on clearly defined infrastructure milestones, rather than assuming that an announced connection capacity guarantees delivery.

These are standard principles of major infrastructure programme management, not claims about Nscale’s actual internal procedures.

4. My verdict

If Nscale committed to a 2027 operating date without reliable evidence that 50 MW of power would be available, that would be a serious failure of project due diligence.

The public reporting makes it reasonable to question the quality of its planning and coordination. It does not, however, prove that Nscale was unaware of the risk, that it deliberately misled Microsoft, or that management ignored a warning.

The decisive evidence would be the original connection offer, the correspondence about the 2026 energisation target, the subsequent revised forecasts, and the date on which Nscale informed Microsoft of the risk.

Those documents would tell us whether this was an unforeseeable deterioration, poor coordination between infrastructure providers, or a failure by Nscale to distinguish a planned connection from deliverable electrical capacity.

My suspicion is that the more fundamental issue was not that Nscale failed to understand how much electricity its data centre needed, but that its commercial delivery plan may have advanced further than its certainty about when that electricity could be supplied. That is the question its board and investors should be asking.

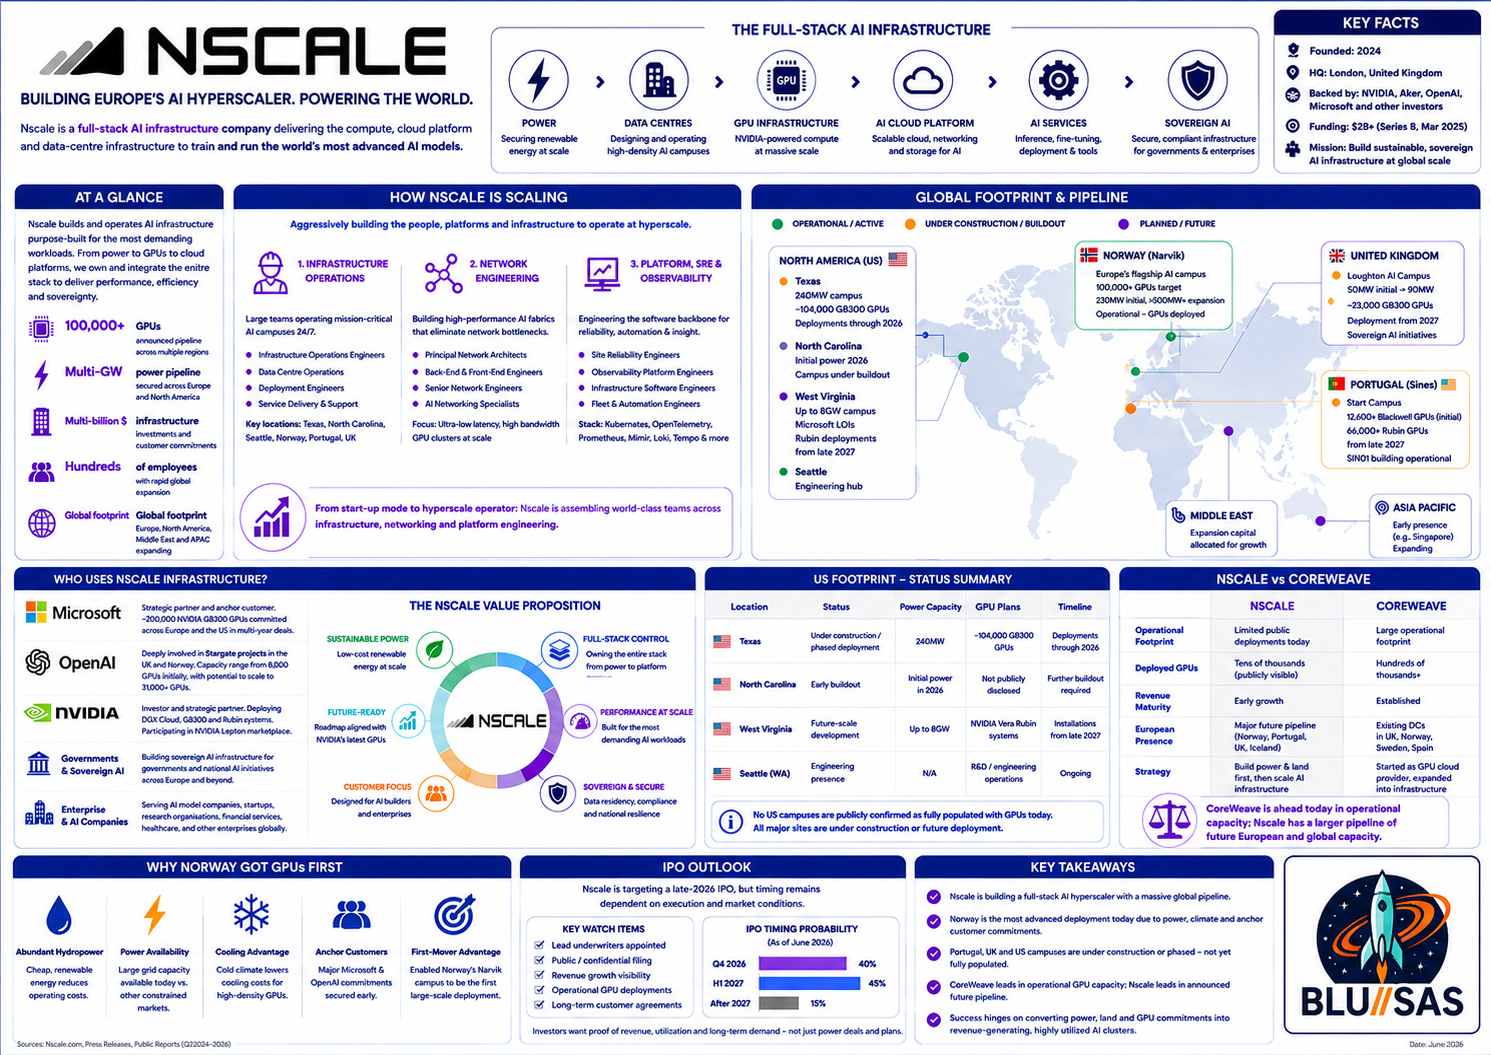
Nscale’s Compute Power

Is there any evidence the Nscale have over 23,000 GB300 GPU to go into the Loughton’s DC?

What the evidence actually shows

There is strong evidence that Nscale planned to deploy 23,040 Nvidia GB300 GPUs at Loughton. There is not, in the public sources I’ve found, equivalent evidence that Nscale had already acquired or physically held all 23,040 GPUs for that site.

Nscale’s own announcement on 16 September 2025 explicitly stated that the Loughton facility would initially house 23,040 GB300 GPUs, with delivery planned for Q1 2027. That establishes a published deployment commitment, not proof of completed procurement or delivery.

Nscale

Evidence by category

EvidenceWhat it establishes
Nscale’s official announcementConfirmed plan: 23,040 GB300 GPUs for Loughton, targeted for Q1 2027.
Nscale’s expanded Microsoft GPU agreementBroader procurement commitment: approximately 200,000 GB300 GPUs across several sites and countries, including about 104,000 for Texas. It does not prove those GPUs were physically available for Loughton. Nscale
IT Pro’s October 2026 reportDelivery uncertainty: the site faced major power delays, and Microsoft withdrew from its agreement for this facility. IT Pro

My conclusion

I would not conclude that Nscale had 23,040 GB300 GPUs sitting in a warehouse waiting for electricity. Equally, the public evidence does not establish that it had failed to procure them.

The key distinction is between contracted GPUs, ordered GPUs, delivered GPUs and installed GPUs. The public announcements establish the intended deployment and broader supply commitments, but not the status of the specific Loughton allocation.

To establish that, we would need a supplier delivery schedule, an Nscale statement confirming the allocation, or physical evidence of the equipment arriving at the site. I haven’t found reliable public evidence confirming any of those for all 23,040 GPUs.

Loughton DC was a building site in April 2026

Yes — and the evidence is stronger than just an empty yard in April.

The key investigation is the Guardian article published on 9 March 2026, titled From press release … to scrap metal site: the Essex ‘supercomputer’ that’s still a scaffolding yard. Reporters visited the site in February 2026 and found it still operating as a scaffolding depot, with scrap metal and lorries rather than an AI data-centre construction project. The article said planning permission was filed in late February, after the newspaper began making enquiries.

The Guardian

The timeline is particularly revealing

Jan 2025

Project announced

The government publicised plans for a major UK AI supercomputer, with an ambitious delivery timetable.

Feb 2026

Still a scaffolding yard

The Guardian’s site visit found no visible data-centre construction underway.

Late Feb 2026

Planning application filed

The application followed the Guardian’s enquiries, according to its investigation.

Oct 2026

Microsoft withdraws

Microsoft pulled out of its Loughton agreement after power-supply problems emerged. Nscale said it remained committed to the project.

The Guardian

What does this tell us about the 23,040 GPUs?

It makes the question about GPU procurement more pressing.

If the site was still a scaffolding yard in February and construction had not begun, then there was no completed facility at Loughton ready to receive and operate those GPUs. That does not prove that the chips had not been purchased, allocated or stored elsewhere.

It does, however, raise a reasonable question: why was the project publicly presented with such an ambitious delivery timetable before the site was visibly progressing through construction and planning?

The strongest evidence here is about the maturity of the physical project, not the precise number of GPUs Nscale had bought.

One qualification: the Guardian’s visit was in February, not April. I have not verified a separate April photograph or site visit, so I would not claim that the March reporting independently establishes the site’s exact condition throughout April.

My assessment: the scaffolding-yard investigation is meaningful early evidence that Loughton was far behind the public image of a rapidly materialising AI supercomputer. Combined with the later power constraints, it suggests that the project’s delivery risk extended beyond electricity alone.

No evidence of over 20,000 GB300 available for the Loughton DC

The most important point is that Nscale had other sites in its Microsoft deployment programme that were intended to host far more GPUs than Loughton. Portugal and Texas are therefore the obvious places to investigate as potential destinations for any Loughton allocation that had actually been procured.

Nscale’s 15 October 2025 announcement gives us a useful starting point:

Nscale

1. Nscale’s announced Microsoft GPU deployments

Texas, USA

104,000 GPUs

Approximately 240 MW initially; phased delivery planned from Q3 2026.

Largest announced deployment in the programme.

Nscale

Sines, Portugal

12,600 GPUs

GB300 deployment planned from Q1 2026 at Start Campus.

A separate facility with a much smaller initial GB300 allocation than Texas.

Nscale

Narvik, Norway

52,000 GPUs

GB300 deployment announced through the Nscale–Aker joint venture.

A major deployment, but actual operating capacity needs to be distinguished from announced capacity.

Nscale

Loughton, UK

23,040 GPUs

50 MW planned, with an original deployment target of Q1 2027.

Microsoft subsequently withdrew from its agreement for this site following power-supply delays.

Nscale

+1

These four announced allocations total approximately 191,600 GPUs, consistent with the broader agreement for approximately 200,000 GPUs once the rounded figures and other programme details are taken into account.

2. How much compute does Nscale actually have?

There is a particularly useful update from Nscale itself. On 1 October 2026, it stated that it had deployed more than 50,000 GPUs powering production workloads across six active data centres in five countries. It said it had deployed 24,000 GPUs in the preceding month alone.

Nscale

Nscale’s reported operational position — 1 October 2026

50,000+

GPUs deployed in production

6

Active data centres

5

Countries

24,000

GPUs deployed in the previous month

Source: Nscale’s own operational update. These are company-reported figures, not an independent audit.

Nscale

That is evidence that Nscale had meaningful live compute capacity. It does not establish that all its announced deployments had been completed or that all 50,000 GPUs were GB300s.

3. Could the 23,040 Loughton GPUs have gone elsewhere?

Potentially, yes — but there is an important timing issue.

Alternative siteAnnounced GB300 allocationPotential to absorb additional GPUs
Texas104,000The largest candidate, subject to installed power, cooling, rack capacity and delivery schedules
Portugal12,600A possible candidate if additional space and power were available
Norway52,000Another potential candidate, subject to actual commissioning progress
Loughton23,040The original allocation; power constraints threatened the planned timetable

The allocations and intended deployment schedules were published by Nscale in October 2025.

Nscale

However, the Loughton GPUs were originally scheduled to arrive from Q1 2027. So we cannot assume that 23,040 GPUs had already been delivered to Nscale and were sitting idle when Microsoft withdrew in October 2026.

There are two different scenarios:

  • If the GPUs had not yet been delivered: Nscale could potentially redirect future shipments to Texas, Portugal or Norway, subject to revised agreements and available infrastructure.
  • If the GPUs had already been delivered or assembled: relocating them would be more complicated. It would require suitable powered racks, cooling, networking, commissioning capacity and potentially contractual changes.

Portugal is particularly interesting because its original 12,600-GPU allocation is smaller than Loughton’s planned 23,040 GPUs. Absorbing the entire Loughton allocation there would require substantially more capacity than the original deployment plan.

4. The bigger question

Nscale’s October update shows that it was deploying compute at considerable speed. But the gap between 50,000 operational GPUs and roughly 200,000 GPUs announced under its Microsoft programme is still substantial.

That gap is not automatically evidence of failure: these are phased deployments with different delivery dates.

The key questions I would want answered are:

  1. How many of the 23,040 Loughton GPUs had actually been ordered, manufactured, delivered or allocated by October 2026?
  2. How many of the 104,000 Texas GPUs and 12,600 Portugal GPUs were installed and available for customer workloads, rather than merely contracted?
  3. Did Nscale have spare powered capacity at any of its existing sites to accommodate additional GPUs?

My conclusion: Nscale had a credible alternative deployment footprint, especially in Texas. But the public evidence does not establish that it possessed 23,040 surplus GPUs or had enough spare capacity elsewhere to deploy them immediately. The most revealing evidence would be its site-by-site GPU deployment figures and delivery schedule, rather than its aggregate contracted GPU count.

Is there going to a successful Nscale IPO this year?

https://fortune.com/2026/09/24/nscale-wants-a-35-billion-valuation-nvidia-is-helping-foot-the-bill

Nscale vs CoreWeave: would Nscale’s IPO succeed?

My assessment, as of 25 October 2026, is that Nscale could complete an IPO, but achieving its reported $35 billion target valuation looks considerably harder following Microsoft’s withdrawal from Loughton. I would expect investors to scrutinise its operational capacity, financing requirements and customer concentration much more closely than they would have a few months ago.

The comparison with CoreWeave is instructive. CoreWeave has demonstrated that investors will fund a specialist AI cloud provider at enormous scale. Its recent share-price weakness also shows that investors are becoming more demanding about how that growth is financed and delivered.

1. Comparing their compute capacity

Figures are from company announcements and recent reporting; contracted capacity is not the same as operational capacity.

CoreWeave

4.2 GW

Contracted power, August 2026

CoreWeave reported approximately 4.2 GW of contracted power and more than $25 billion in additional customer commitments during early Q3 2026. It is an established, publicly traded AI cloud provider with a substantial operating business.

CoreWeave Investors

Nscale

55 MW

Combined capacity across five active data centres, according to its IPO prospectus

Nscale’s September prospectus reported five active data centres with 55 MW of combined capacity and 12 more at various stages of development. Its subsequent October update reported more than 50,000 GPUs in production across six active data centres in five countries.

DCD

+1

The power figures alone illustrate the difference in scale:

Reported or contracted power capacity

CoreWeave contracted power versus Nscale’s reported active-site capacity; these are different measures and are not a like-for-like comparison.
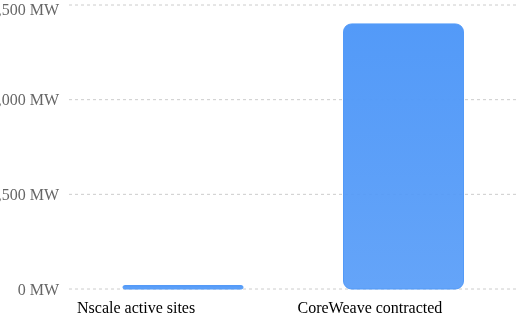
CoreWeave’s contracted power is approximately 76 times Nscale’s prospectus-reported active-site capacity. That is not a claim that CoreWeave has 76 times as much usable compute today: one figure is contracted power and the other is reported active-site capacity.

The GPU counts are also not directly comparable. Nscale has publicly reported more than 50,000 GPUs in production, but the figures cited here do not establish a matching, current CoreWeave GPU count on the same basis. Power capacity, GPU generation, utilisation and customer workloads all matter.

2. CoreWeave’s share-price decline: what is the market telling us?

Recent market developments, October 2026

CoreWeave

AI cloud provider

−15.1%

14–15 October sell-off period

Reuters reported that CoreWeave shares fell sharply as concerns grew over its debt burden, rising borrowing costs and the profitability of AI infrastructure investment. Its bonds also sold off, with yields reaching approximately 15%.

Investing.com

The decline is a warning, but not necessarily evidence that customers no longer want AI compute.

Investors are increasingly distinguishing three things:

  • Demand: Do customers want GPU capacity?
  • Delivery: Can the provider bring the contracted capacity online on time?
  • Returns: Will the resulting revenue cover equipment costs, electricity, financing, depreciation and operating expenses?

CoreWeave has demonstrated substantial demand and operating scale. Nevertheless, its debt and capital expenditure have made investors question whether growth will produce attractive returns.

Nscale faces the same questions, but with an additional disadvantage: it has a much smaller operational footprint and a greater proportion of its valuation depends on infrastructure that is still being developed.

3. Why Nscale’s $35 billion IPO valuation is vulnerable

The most concerning figures in Nscale’s IPO reporting are its revenue, losses and concentration of future contracts.

Nscale, first half of 2026

$140.6m

Revenue

$1.02bn

Net loss

$103bn

Reported total contract value

~85%

Of contract commitments attributed to Microsoft and Anthropic combined in September reporting

Sources: Nscale’s IPO reporting and TechCrunch’s analysis. Total contract value is not recognised revenue, cash received or guaranteed profit.

The Information

This is the central valuation problem: a large contract backlog looks attractive only if Nscale can finance, build and operate the capacity needed to fulfil it.

The Information reported on 29 September that Nscale’s $35 billion valuation target looked too high given the proportion of contracts dependent on unbuilt data centres. It suggested a valuation of less than half that figure might be more appropriate.

The Information

The Microsoft withdrawal does not erase the entire $103 billion backlog. Reports indicate that the Loughton project represented only a small part of that total, and Nscale has said its other Microsoft contracts remain in place. But it damages confidence in execution.

There is another important complication: the IPO process itself. On 23 October, Quartz reported that Nscale’s IPO marketing remained on hold while it addressed SEC feedback, amid investor resistance to the proposed valuation. The same report noted that CoreWeave had lost approximately a quarter of its share value during October.

Quartz

4. My IPO forecast

These are my subjective scenario estimates, not market-implied probabilities or investment advice.

Bull case

20%

$25–35bn valuation

Nscale secures alternative power for Loughton, delivers major projects on schedule, maintains customer contracts and convinces investors that its backlog will translate into revenue.

Base case

50%

$15–25bn valuation

The IPO proceeds, but at a materially lower valuation or with less favourable terms. Investors recognise the opportunity while pricing in construction, funding and customer-concentration risks.

Bear case

30%

Below $15bn, or a delayed IPO

Financing becomes more expensive, construction delays spread, customers reconsider commitments, or public-market investors refuse to underwrite the proposed growth rate.

Scenario ranges are analytical estimates based on information available on 25 October 2026. They are not independently established fair values. Probabilities sum to 100% and describe the valuation/outcome scenarios, not the probability of Nscale ultimately becoming a successful business.

My central estimate would therefore be a valuation of approximately $15–25 billion if Nscale successfully completes an IPO in the current environment. I would be sceptical of $35 billion without strong evidence of funded construction, reliable energisation dates and a credible path to profitability.

5. What would change my mind?

The following evidence would materially improve my assessment:

  1. Operational capacity: independently verifiable figures for installed GPUs, billable compute and utilisation by site.
  2. Power certainty: binding, credible power-delivery schedules for major sites, especially Norway and Portugal.
  3. Funding: sufficient committed capital to complete the build programme without excessive dilution or punitive debt.
  4. Customer resilience: evidence that Microsoft and Anthropic commitments are firm, financeable and deliverable, with manageable termination conditions.
  5. Unit economics: gross margins and cash generation that improve as new facilities become operational.

The converse is also true. Further missed delivery milestones, expensive emergency financing or additional customer withdrawals would make a valuation below $15 billion—or a postponement—more plausible.

Final verdict

CoreWeave’s share-price decline is a useful warning about the market’s appetite for capital-intensive AI infrastructure companies. But it is not a simple referendum on AI demand: investors are increasingly penalising debt, execution risk and the gap between promised capacity and profitable operating compute.

Nscale’s risk is more acute because it is asking public investors to value a much smaller operating business partly on the basis of an enormous future contract backlog. Microsoft’s Loughton withdrawal reinforces precisely the concern that investors already had: a contract is not the same as a working data centre, and a working data centre is not automatically a profitable one.

I would expect Nscale to face pressure to reduce its valuation expectations substantially. A successful IPO remains possible, but a $35 billion flotation now looks like the optimistic case rather than the most likely outcome.
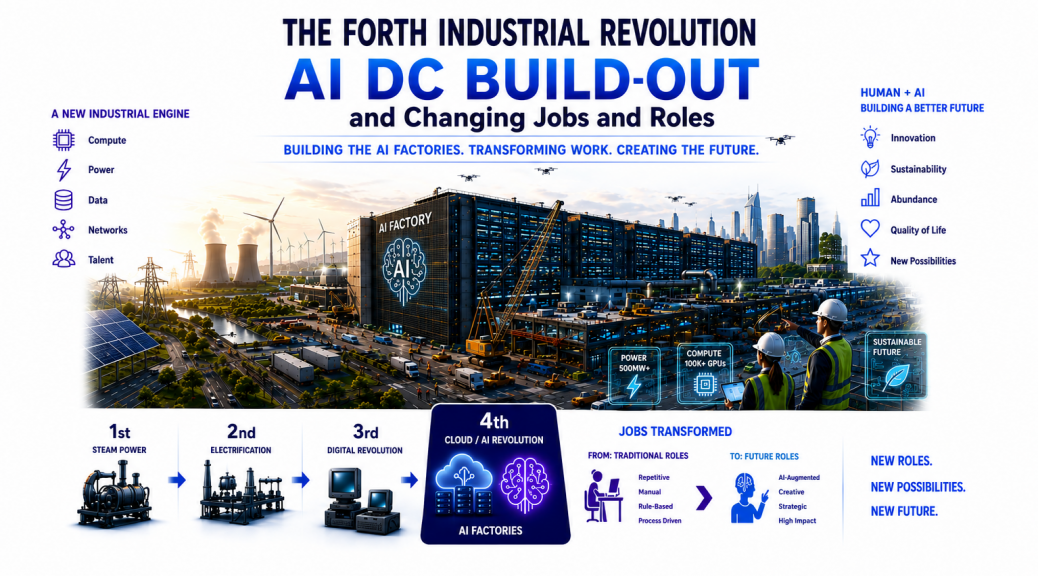
AI DC Buildouts, Changing Jobs & Roles of the 4th Industrial Revolution

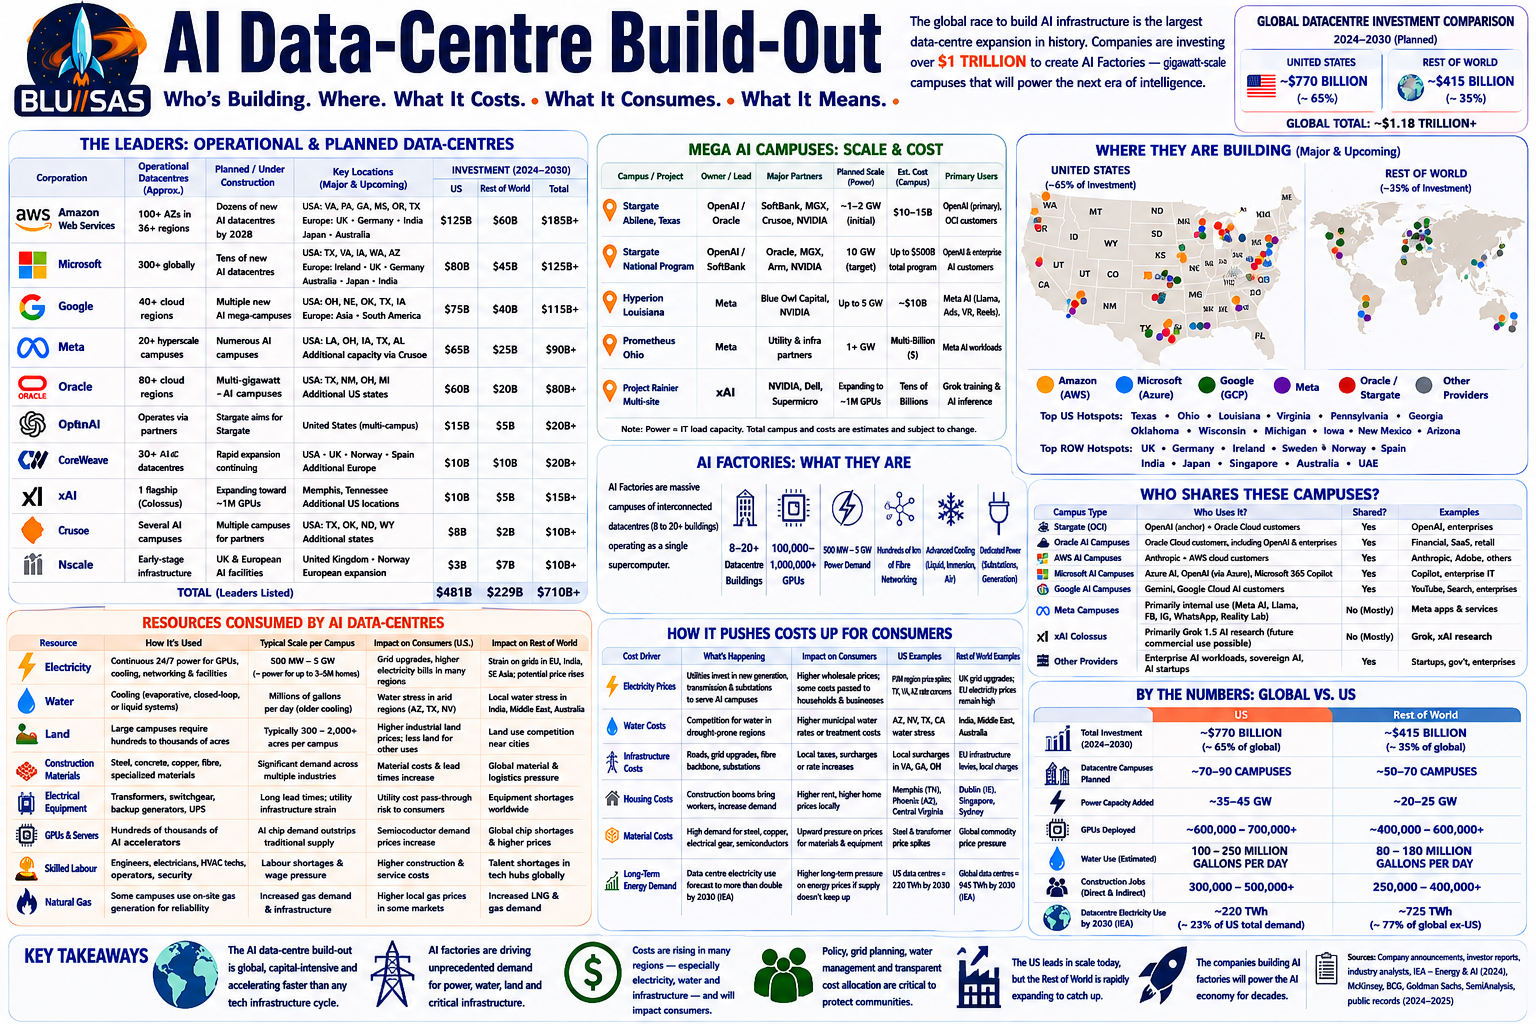
The AI infrastructure race is being led by a relatively small number of corporations, but together they represent well over US$1 trillion of planned investment over the remainder of this decade. Many figures below are approximate because companies often announce campuses or regions rather than exact building counts, and projects evolve rapidly.

CorporationOperational data centres (approx.)AI data centres planned / under constructionMain locations
Amazon Web Services100+ availability zones across 36+ regionsDozens of new AI campuses through 2028 (including Project Rainier)USA (Virginia, Pennsylvania, Georgia, Mississippi, Oregon), Europe, UK, Germany, India, Japan, Australia
Microsoft300+ data centres globallyTens of new AI campuses; ~$80B AI infrastructure investmentUSA, Sweden, Finland, UK, Germany, Australia, Japan, Texas, Wisconsin
Google40+ cloud regions and many hyperscale campusesMultiple new AI mega-campusesOhio, Nebraska, Oklahoma, Texas, Iowa, Europe, Asia
Meta20+ hyperscale campusesNumerous AI campuses under expansionLouisiana, Ohio, Iowa, Texas, Alabama, with additional capacity from Crusoe
Oracle80+ cloud regionsMulti-gigawatt AI campuses via Stargate plus Oracle Cloud expansionTexas, New Mexico, Ohio, Michigan and other US states
OpenAIOperates via partners rather than owning a global DC fleetStargate aims for roughly 20 major AI campusesTexas, New Mexico, Ohio, Wisconsin, Michigan and additional US sites
SoftBankNo major hyperscale cloud estateCo-investor in StargateUnited States (multiple campuses)
CoreWeave~30+ AI data centresContinuing rapid expansionUSA, UK, Norway, Spain and additional European sites
xAI1 flagship AI supercluster (Colossus) plus expansionsExpanding toward one million GPUsMemphis, Tennessee and additional US locations
CrusoeSeveral AI campuses under operationMultiple campuses for OpenAI, Meta and MicrosoftTexas, Oklahoma and other US states
NscaleEarly-stage AI infrastructureUK and European sovereign AI facilities plannedUnited Kingdom, Norway and Europe (build-out still in early stages)

Where the biggest build-out is happening

The current hotspots are:

  • Texas – by far the largest concentration, with Stargate, Oracle, Microsoft, Google and xAI all investing heavily.
  • Ohio – Google, Meta and Oracle are all expanding there.
  • Louisiana – Meta’s enormous AI campus.
  • Virginia – still the world’s largest concentration of conventional cloud data centres.
  • Pennsylvania, Georgia and Oklahoma – major AWS and Google investments.
  • Wisconsin, Michigan and New Mexico – emerging AI infrastructure hubs.

The scale is unprecedented

The six largest AI infrastructure builders (Amazon, Microsoft, Google, Meta, Oracle and the Stargate consortium) have collectively committed around US$690–700 billion in AI-related capital expenditure, with 74 new AI-focused projects breaking ground in the US during 2026 alone. Longer-term projections suggest total AI infrastructure investment could exceed US$5 trillion globally by 2030.

One notable trend is that these companies are no longer building isolated data centres. They are constructing AI campuses consisting of anywhere from 8 to more than 20 individual data-centre buildings, all linked by ultra-high-speed networking so they function as a single giant AI supercomputer. A single campus can consume 500 MW to over 1 GW of power, equivalent to the electricity demand of a medium-sized city.

The largest AI campuses consume enormous quantities of resources. Some impacts are already measurable, while others remain uncertain and depend on how utilities allocate costs. It’s important to distinguish local effects (which can be substantial) from national effects (which are often much smaller).

ResourceHow AI campuses use itImpact on consumers
ElectricityHundreds of MW to several GW continuouslyHigher utility investment, possible higher electricity bills in constrained regions, increased need for new power stations
WaterCooling systems can consume millions of gallons per day, although newer designs increasingly use closed-loop or air coolingCompetition for water in drought-prone areas; pressure on municipal supplies
LandCampuses often occupy hundreds to thousands of acresIndustrial land values rise; reduced land available for other development
Construction materialsSteel, concrete, copper, fibre-optic cableHigher demand can contribute to material price increases, though AI is only one of several drivers
Electrical equipmentTransformers, switchgear, substationsLonger lead times for utilities and industrial customers
GPUs and serversHundreds of thousands of accelerators per campusSemiconductor manufacturing capacity diverted toward AI, increasing demand for advanced chips
Skilled labourElectrical engineers, construction workers, data-centre techniciansWage competition and labour shortages in some regions
Natural gasSome campuses are building dedicated gas-fired generationIncreased demand for gas infrastructure and fuel in certain markets

Electricity prices

Electricity is the area where households are most likely to notice an effect.

Large AI campuses require utilities to invest in:

  • New transmission lines
  • New substations
  • Additional generation
  • Grid upgrades

Who pays depends on regulation.

In some regions, regulators are trying to ensure that AI companies pay most of these costs. In others, some infrastructure costs are spread across all customers, which can increase household bills.

For example:

RegionReported effect
PJM (eastern U.S.)Wholesale electricity prices rose sharply as demand from AI data centres increased, prompting calls for tech companies to fund more of the required infrastructure.
ArizonaUtilities warn that electricity infrastructure may need to roughly double within a few years because of AI growth.
VirginiaData centres already account for a very large share of electricity demand in some parts of the state.

It’s also worth noting that recent academic work found that, historically (2015–2024), data centres slightly reduced average U.S. electricity prices by helping spread fixed grid costs over more customers. The authors caution that this may not hold if future supply constraints become severe.

Water

Water is highly location-dependent.

Older evaporative cooling systems can use several million gallons of water per day. Newer AI facilities increasingly employ:

  • Closed-loop liquid cooling
  • Direct-to-chip liquid cooling
  • Air cooling where practical

These approaches can significantly reduce freshwater consumption, but water remains a concern in arid regions.

Housing

AI campuses can affect local housing markets by:

  • Bringing thousands of construction workers
  • Creating highly paid engineering jobs
  • Increasing demand for rental accommodation

The effect is usually local rather than national.

Employment

Benefits include:

  • Construction employment
  • Electrical contracting
  • Operations and maintenance jobs
  • Security
  • Network engineering
  • Mechanical engineering

However, once operational, AI campuses employ far fewer people than factories of similar size.

Have prices increased?

Evidence is mixed:

ItemObserved trend
ElectricitySome U.S. regions have seen higher wholesale prices and concerns about retail bills where AI demand is concentrated.
WaterMostly local impacts in water-stressed regions rather than broad consumer price rises.
HousingLocal increases around major developments are common, though driven by multiple factors.
Construction materialsIncreased demand contributes to pressure, but AI is only one of many drivers.
Consumer goodsThere is currently little evidence that AI data centres have directly increased the prices of everyday retail goods.

Overall, the greatest measurable impact today is on electricity infrastructure. The International Energy Agency projects that global data-centre electricity consumption will more than double to about 945 TWh by 2030, driven largely by AI. Whether households ultimately pay more depends on regulatory decisions about who funds the new power plants, transmission lines and substations needed to support these AI campuses.

Changing Jobs and Roles

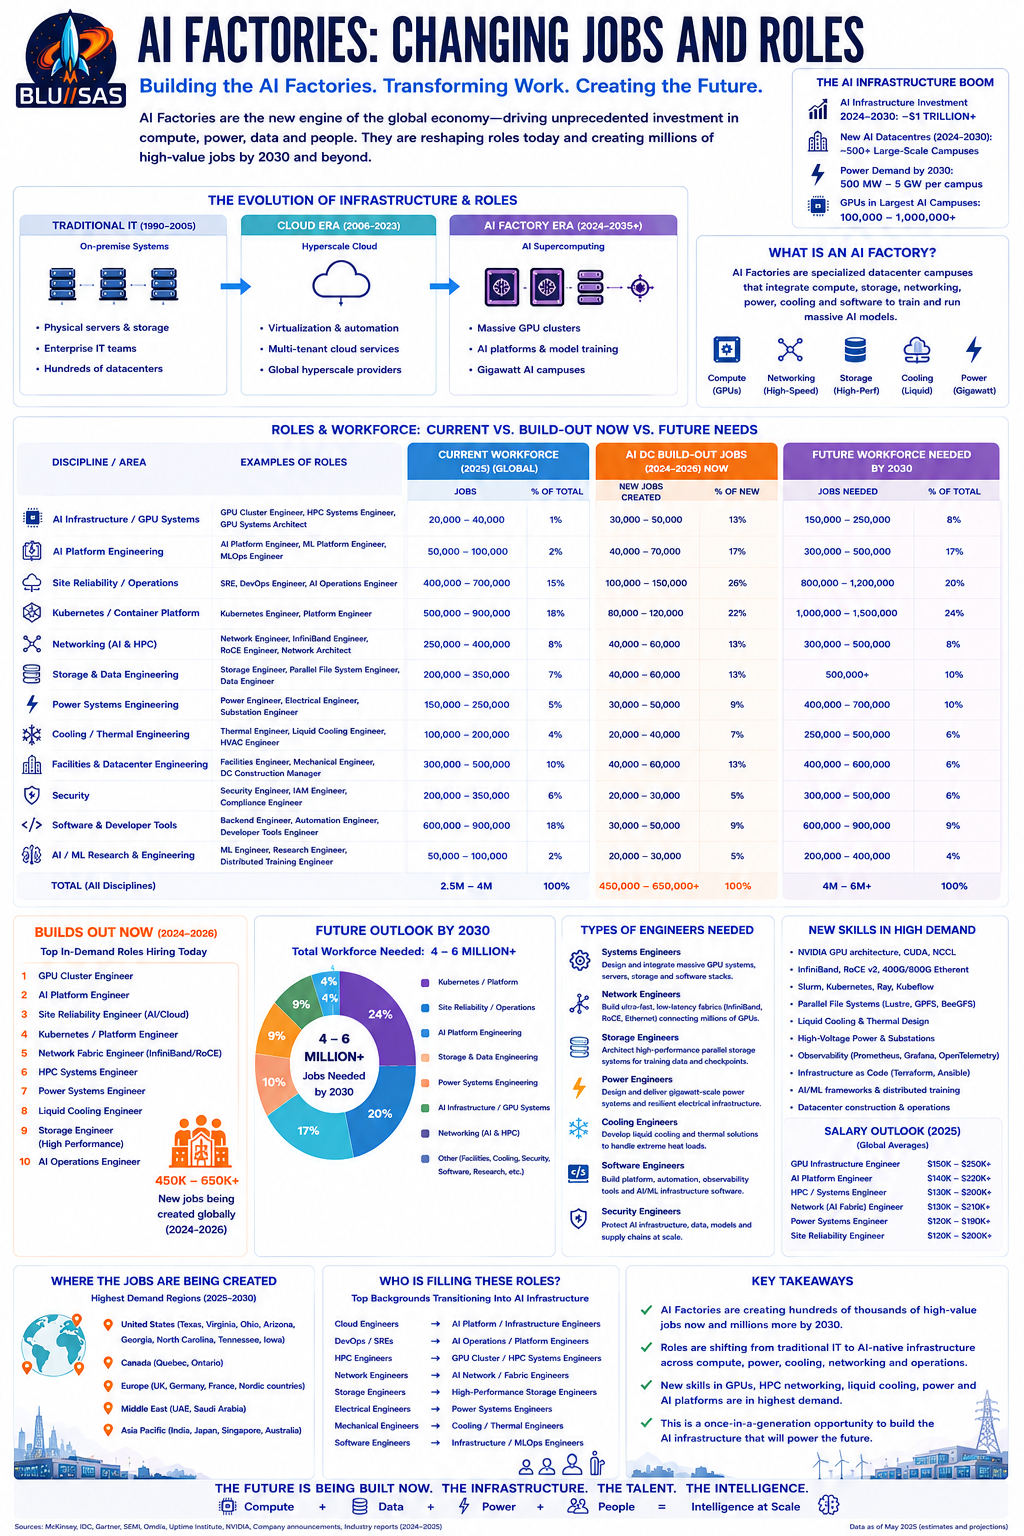
The AI infrastructure boom is creating the largest shift in infrastructure engineering since the rise of public cloud around 2006–2015. Traditional cloud providers needed engineers to build reliable, scalable services for virtual machines, storage and networking. AI Factories require all of that plus expertise in GPUs, ultra-high-speed networking, power engineering, liquid cooling and AI software platforms.

Evolution of Infrastructure Engineering

EraPrimary GoalMain InfrastructureTypical Employer
Enterprise IT (1990–2010)Business applicationsServers, SAN, LANBanks, government, enterprises
Cloud (2006–2024)Multi-tenant cloud servicesHyperscale datacentersAWS, Azure, Google Cloud
AI Factory (2024–2035+)Massive AI computationGPU supercomputers, AI campusesOpenAI, Meta, xAI, Oracle, CoreWeave, Nscale, AWS

Traditional Cloud Provider Jobs

Cloud providers traditionally organised engineering into around a dozen major disciplines.

DisciplineTypical Roles
Datacenter FacilitiesFacilities Engineer, Mechanical Engineer, Electrical Engineer
ComputeServer Engineer, Linux Engineer, Virtualisation Engineer
StorageStorage Engineer, Ceph Engineer, SAN Engineer
NetworkingNetwork Engineer, Network Architect
Cloud PlatformKubernetes Engineer, OpenStack Engineer, VMware Engineer
ReliabilitySite Reliability Engineer (SRE), DevOps Engineer
SecuritySecurity Engineer, IAM Engineer
ObservabilityMonitoring Engineer, Logging Engineer
AutomationAnsible Engineer, Terraform Engineer
SoftwareBackend Engineer, Platform Engineer
OperationsNOC Engineer, Incident Manager
CapacityCapacity Planner, Performance Engineer

A large hyperscale datacenter typically employs 100–300 permanent staff, with many more contractors during construction.


AI Factory Engineering

AI Factories introduce entirely new engineering domains.

New DisciplineExample Roles
GPU InfrastructureGPU Systems Engineer, GPU Cluster Engineer
AI NetworkingInfiniBand Engineer, RoCE Engineer, Ethernet Fabric Engineer
AI StorageHigh-performance Storage Engineer, Parallel Filesystem Engineer
AI CoolingLiquid Cooling Engineer, Thermal Systems Engineer
AI SchedulingSlurm Engineer, Kubernetes AI Platform Engineer
AI RuntimeCUDA Engineer, Distributed Training Engineer
AI OptimisationML Infrastructure Engineer
AI Datacenter PowerHigh-voltage Power Engineer
AI Chip EngineeringAccelerator Integration Engineer
AI OperationsAI Infrastructure SRE

Engineering Stack

Traditional cloud:

Applications
Containers
Virtual Machines
Hypervisor
Servers
Storage
Networking
Power

AI Factory:

AI Models
Distributed Training
Kubernetes / Slurm
CUDA / ROCm
100,000+ GPUs
InfiniBand / RoCE
Parallel Storage
Liquid Cooling
Gigawatt Power

Traditional Cloud Skills

  • Linux
  • VMware
  • Kubernetes
  • OpenStack
  • AWS
  • Azure
  • Terraform
  • Ansible
  • Prometheus
  • Grafana
  • Python
  • Go
  • Storage
  • Networking

New AI Factory Skills

Additional skills now becoming highly valuable include:

  • NVIDIA GPU architecture
  • AMD Instinct
  • CUDA
  • NCCL
  • GPUDirect RDMA
  • InfiniBand
  • RoCE v2
  • Slurm
  • Ray
  • Kubeflow
  • MLFlow
  • Triton Inference Server
  • Parallel file systems (Lustre, IBM Storage Scale/GPFS, BeeGFS)
  • High-performance Ethernet (400/800 GbE)
  • Direct-to-chip liquid cooling
  • Rack-scale power engineering

Jobs Growing Fastest

RoleGrowth Outlook
GPU Infrastructure EngineerExtremely High
AI Platform EngineerExtremely High
HPC Systems EngineerExtremely High
Kubernetes Platform EngineerVery High
Storage EngineerVery High
Site Reliability EngineerVery High
Network Fabric EngineerExtremely High
Power Systems EngineerExtremely High
Mechanical Cooling EngineerExtremely High
AI Operations EngineerExtremely High

Approximate Current Workforce (2025–2026)

The exact numbers are difficult to measure because many roles overlap, but industry estimates suggest:

ProfessionEstimated Global Workforce
Cloud Engineers2–3 million
DevOps Engineers1.5–2 million
Site Reliability Engineers400,000–700,000
Kubernetes Engineers500,000–900,000
Datacenter Engineers300,000–500,000
Storage Engineers200,000–350,000
HPC Engineers80,000–150,000
GPU Infrastructure Specialists20,000–40,000
AI Infrastructure Engineers50,000–100,000

Estimated Workforce Needed by 2030

As AI campuses proliferate worldwide, demand is expected to increase significantly.

ProfessionEstimated Demand by 2030
AI Infrastructure Engineers300,000–500,000
GPU Cluster Engineers150,000–250,000
HPC Engineers250,000–400,000
SREs (AI/Cloud)800,000–1.2 million
Kubernetes Platform Engineers1–1.5 million
Network Fabric Engineers300,000–500,000
Storage Engineers500,000+
Power Engineers400,000–700,000
Cooling Engineers250,000–500,000

These are indicative estimates derived from announced AI infrastructure expansion plans and broader industry workforce analyses rather than official forecasts.


Where the Talent Is Coming From

Most AI Factory engineers are not newly trained graduates. Companies are recruiting experienced professionals from adjacent disciplines:

Previous RoleTransition To
Cloud EngineerAI Platform Engineer
Kubernetes EngineerAI Infrastructure Engineer
SREAI Operations Engineer
HPC EngineerGPU Cluster Engineer
Linux EngineerGPU Systems Engineer
Network EngineerInfiniBand/RoCE Fabric Engineer
Storage EngineerAI Storage Architect
OpenStack EngineerAI Cloud Platform Engineer
Ceph EngineerHigh-performance Storage Engineer
DevOps EngineerML Platform Engineer

Why This Matters

The next decade is likely to see a shift similar to the transition from enterprise IT to cloud computing. During the 2010s, the most sought-after roles were Cloud Engineers, DevOps Engineers and SREs. Through the late 2020s and into the 2030s, many of the highest-demand infrastructure roles are expected to centre on AI Factories: designing, building and operating gigawatt-scale GPU campuses, high-performance storage systems, ultra-low-latency networks and AI platforms.

For someone with expertise in Linux, Kubernetes, observability, automation, storage and cloud infrastructure, the progression into AI infrastructure engineering is relatively direct. Adding knowledge of GPU platforms, HPC networking (InfiniBand/RoCE), parallel storage (such as Lustre or GPFS), Slurm, CUDA and liquid-cooled datacenter design positions engineers for many of the roles expected to see the strongest demand over the coming decade.

Part of the 4th Industrial Revolution

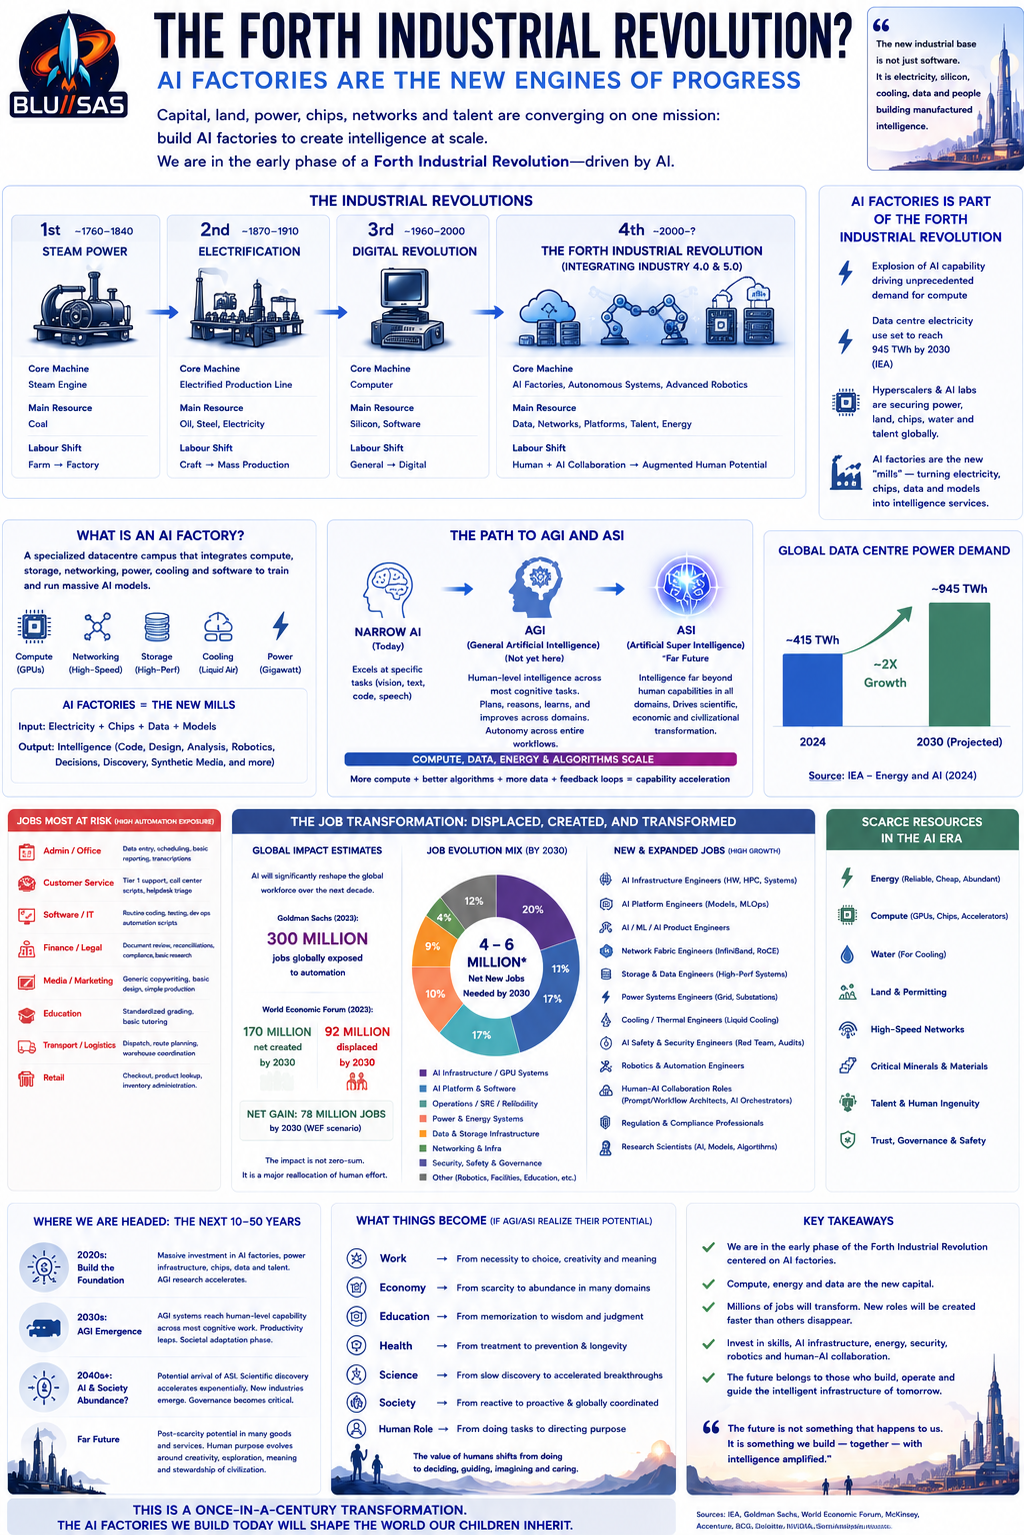
Yes — this is plausibly the tail-end phase of the Forth Industrial Revolution, but with one caveat: we do not yet know whether AGI/ASI will arrive, or when. What is clear is that capital, land, power, water, chips, networks and engineering labour are being redirected toward AI factories.

The simplest framing:

Industrial phaseCore machineMain resourceMain labour shift
1stSteam engineCoalFarm → factory
2ndElectrified production lineOil, steel, electricityCraft → mass production
3rdComputerSilicon, softwareClerical → digital
4thCloud + automationData, networks, platformsIT → cloud/SRE/DevOps
5thAI factoryCompute, power, GPUs, dataHuman labour → AI-augmented/AI-directed labour

The AI factory is the new “mill.” Instead of spinning cotton or stamping cars, it converts electricity + chips + data + models into intelligence services: code, design, analysis, customer support, robotics control, synthetic media, drug discovery and eventually autonomous decision systems.

The resource pull is already visible. The IEA projects global data-centre electricity consumption could roughly double to about 945 TWh by 2030, growing far faster than general electricity demand. That is why hyperscalers, AI labs and neoclouds are racing to secure power, grid connections, GPUs, cooling, land and engineering staff.

On jobs, the likely pattern is not “all jobs disappear.” It is task compression: fewer people needed for routine cognitive work, more people needed for infrastructure, supervision, security, robotics, energy, regulation and high-complexity design. Goldman Sachs has estimated that AI could expose the equivalent of 300 million full-time jobs globally to automation, while the World Economic Forum projects by 2030 about 170 million roles created and 92 million displaced, for a net gain of 78 million under its surveyed-employer scenario.

Likely traditional jobs under pressure:

AreaJobs most exposed
Admin/officeData entry, scheduling, basic document processing
Customer serviceTier-1 support, call-centre scripts, helpdesk triage
SoftwareBoilerplate coding, simple QA, basic web/app work
Finance/legalDocument review, reconciliation, compliance paperwork
Media/marketingGeneric copywriting, SEO text, simple design production
EducationBasic tutoring, marking, lesson-content generation
Transport/logisticsDispatch, route planning, warehouse coordination
RetailCheckout, product support, inventory admin

New and expanded jobs:

Future areaRoles likely to grow
AI infrastructureGPU cluster engineer, AI SRE, AI platform engineer
Power/gridSubstation engineer, energy systems engineer, microgrid operator
Cooling/facilitiesLiquid-cooling engineer, thermal engineer, datacenter mechanic
NetworkingInfiniBand/RoCE engineer, optical network engineer
Storage/dataParallel storage engineer, data governance engineer
AI safety/securityModel auditor, AI red-team engineer, AI incident responder
RoboticsRobot fleet supervisor, autonomy technician, human-robot workflow designer
RegulationAI compliance officer, algorithmic accountability auditor
Human-AI workAgent orchestrator, prompt/workflow architect, AI operations manager
Synthetic worldsSimulation designer, digital twin engineer, synthetic-data engineer

If AGI arrives, the shift accelerates. If ASI arrives, the shift becomes civilisational: the scarce resources may become energy, compute rights, physical materials, robotics capacity, trusted governance and human legitimacy, rather than ordinary labour.

So yes: the AI build-out looks like the physical foundation of a Fifth Industrial Revolution — not just software, but a new industrial base built around manufactured intelligence.

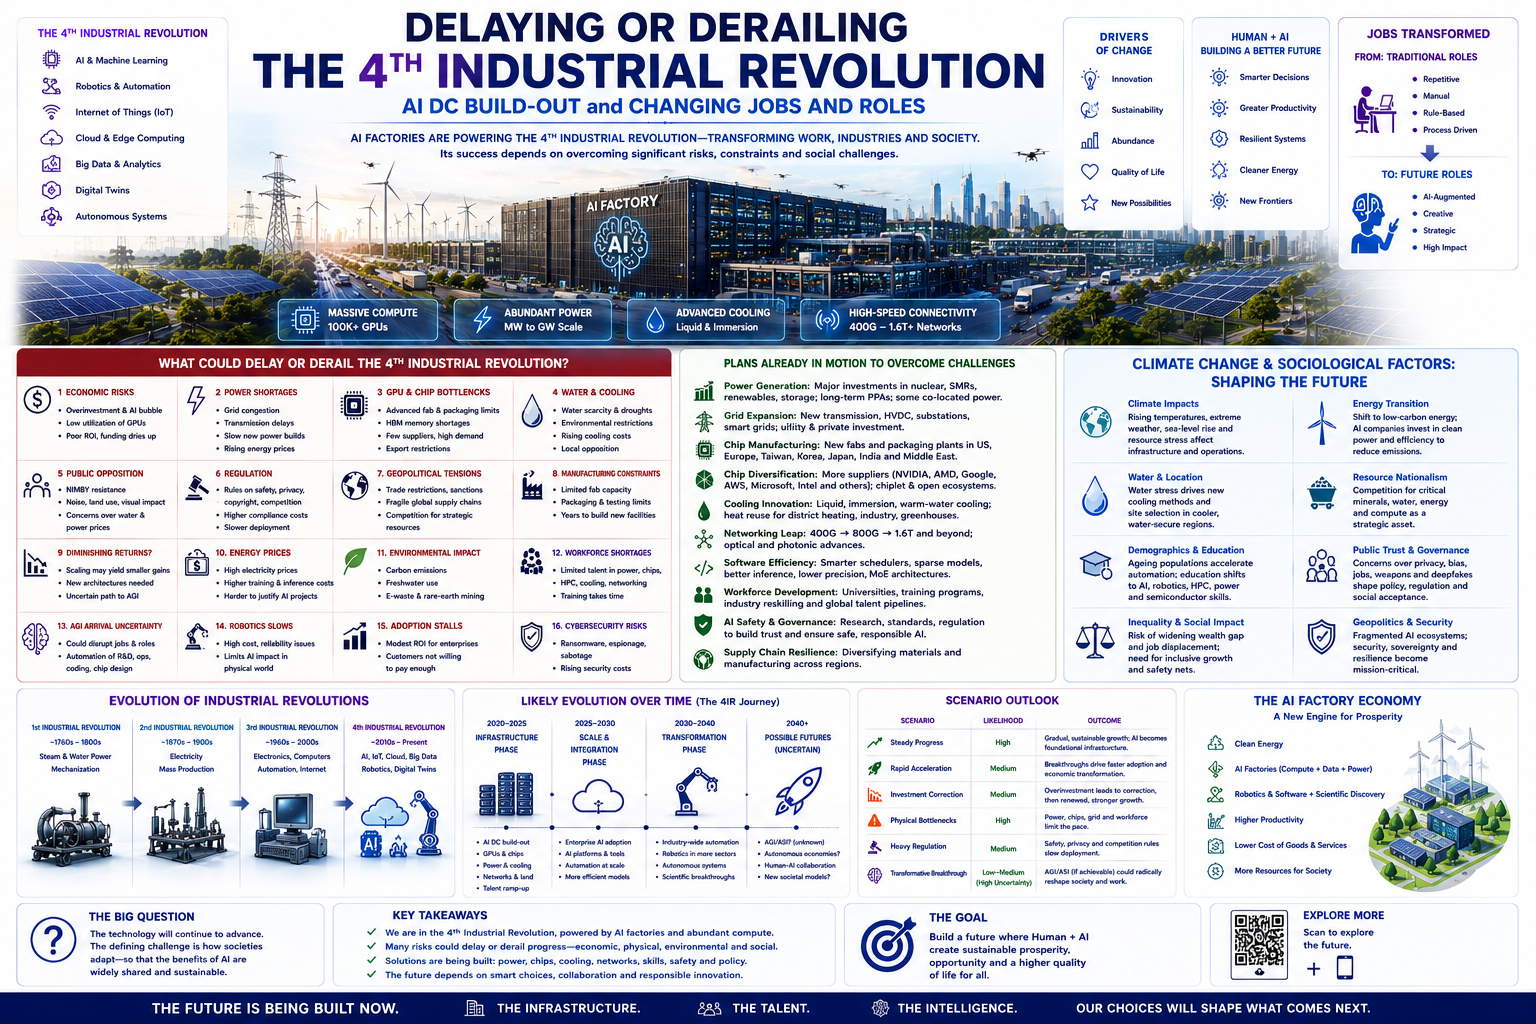
Climate change and broader sociological factors are arguably the largest long-term uncertainties for the Fifth Industrial Revolution. Unlike technical bottlenecks, they can alter not just the pace of AI adoption but also where, how, and for whom AI infrastructure is built.

I don’t think climate change will stop the AI revolution, but it could fundamentally reshape it. History suggests industrial revolutions adapt to resource constraints rather than ending because of them.

Climate change

1. Energy transition

Today’s AI factories consume enormous amounts of electricity.

If climate policies tighten globally, AI companies may no longer be able to rely on inexpensive fossil-fuel generation.

This is already pushing investment towards:

  • Nuclear power
  • Small Modular Reactors (SMRs)
  • Geothermal
  • Offshore wind
  • Utility-scale solar
  • Long-duration batteries
  • Grid-scale storage

By the 2040s, a successful AI company may be judged as much by its carbon intensity per AI token as by its model quality.


2. Water shortages

Many AI campuses currently use water-intensive cooling.

Increasing droughts could force AI factories to relocate.

Future AI campuses are likely to favour:

  • Scotland
  • Norway
  • Sweden
  • Finland
  • Iceland
  • Canada
  • Pacific Northwest
  • Patagonia

Cool climates reduce cooling costs while providing more reliable water supplies.


3. Sea-level rise

Many current datacentres sit near coasts because they benefit from:

  • Fibre landing stations
  • Major cities
  • Existing infrastructure

Over decades, flood risks may encourage more inland development.


4. Extreme weather

Increasingly frequent:

  • Heatwaves
  • Wildfires
  • Hurricanes
  • Flooding

all increase operational risks.

Future campuses may need:

  • Greater redundancy
  • Fire-resistant designs
  • Multiple grid connections
  • Larger battery systems
  • Independent power generation

Resource nationalism

Countries increasingly recognise compute as a strategic asset.

Competition may intensify over:

  • Lithium
  • Copper
  • Rare earth elements
  • Uranium
  • Semiconductor-grade silicon
  • Freshwater
  • Electricity

The next century may see competition over compute capacity much as the twentieth century saw competition over oil.


Demographics

Many developed nations face ageing populations.

This may actually accelerate AI adoption.

Examples include:

  • Japan
  • South Korea
  • Germany
  • Italy

If fewer working-age people are available, automation becomes economically attractive.


Education

Universities are already adapting.

Future curricula may emphasise:

  • AI engineering
  • Robotics
  • HPC
  • Power engineering
  • Semiconductor engineering
  • AI governance

Routine programming skills alone may become less valuable than systems integration, critical thinking and domain expertise.


Public trust

AI adoption depends heavily on social acceptance.

Concerns include:

  • Surveillance
  • Privacy
  • Bias
  • Deepfakes
  • Autonomous weapons
  • Job displacement

Public backlash could lead to stricter regulation or slower deployment in some sectors.


Wealth inequality

One of the most significant risks is that AI could concentrate wealth among those who own:

  • AI models
  • Compute infrastructure
  • Semiconductor intellectual property
  • Energy assets
  • Data

If productivity gains are not widely shared, inequality could increase.

Possible policy responses include:

  • Expanded education and retraining
  • Wage insurance
  • Stronger competition policy
  • Tax reforms
  • New social safety nets

Different countries are likely to pursue different approaches.


Employment transition

Industrial revolutions historically eliminate some jobs while creating others.

The challenge is timing.

If AI removes work faster than new roles appear, societies may experience:

  • Higher unemployment
  • Political instability
  • Reduced consumer spending
  • Pressure for labour-market reforms

Managing this transition is likely to be one of the defining policy challenges of the coming decades.


Geopolitics

Compute is becoming a strategic resource.

This may encourage blocs centred around:

  • North America
  • Europe
  • China
  • India
  • Middle East

Each could develop increasingly independent AI ecosystems, supply chains and regulations.


Alternative futures

ScenarioAI build-outSociety
Green AI RevolutionAI powered largely by low-carbon energy; highly efficient hardwareAI helps accelerate decarbonisation and scientific progress
AI Arms RaceNational security drives rapid expansion despite environmental costsFragmented AI ecosystems and geopolitical competition
AI BubbleInfrastructure investment slows after poor returnsAI remains important but grows more gradually
Climate Adaptation AIAI prioritises climate modelling, energy optimisation and resilient infrastructureAI becomes a key tool for adapting to climate change
Post-Scarcity Transition (speculative)Abundant clean energy and highly capable AI dramatically reduce production costsWork shifts towards creativity, care, governance and exploration

The “AI Factory Economy”

A useful way to think about the long term is that AI factories may become a new class of critical infrastructure, similar to:

  • Power stations
  • Railways
  • Ports
  • Telecommunications
  • The Internet

The economy could evolve around interconnected systems:

Clean Energy
│
▼
AI Factories
│
▼
Robotics + Software + Scientific Discovery
│
▼
Higher Productivity
│
▼
Lower Cost of Goods and Services
│
▼
More Resources Available for Society

That is an optimistic pathway. A less favourable outcome is also possible if productivity gains are unevenly distributed, infrastructure cannot keep pace, or environmental constraints become more severe.

The most important sociological question

The defining issue may not be whether AI becomes powerful enough—it almost certainly will continue to improve significantly. The larger question is who benefits from the productivity gains.

Previous industrial revolutions eventually raised average living standards, but they also brought decades of disruption, labour conflict and institutional change. The Fifth Industrial Revolution, if it unfolds as many expect, is likely to follow a similar pattern: technological progress may be rapid, but the economic and social institutions needed to distribute its benefits will evolve more slowly.

In other words, the success of the Fifth Industrial Revolution may depend less on building bigger AI factories and more on how societies adapt their education systems, labour markets, energy infrastructure and governance to make effective use of the capabilities those AI factories create.

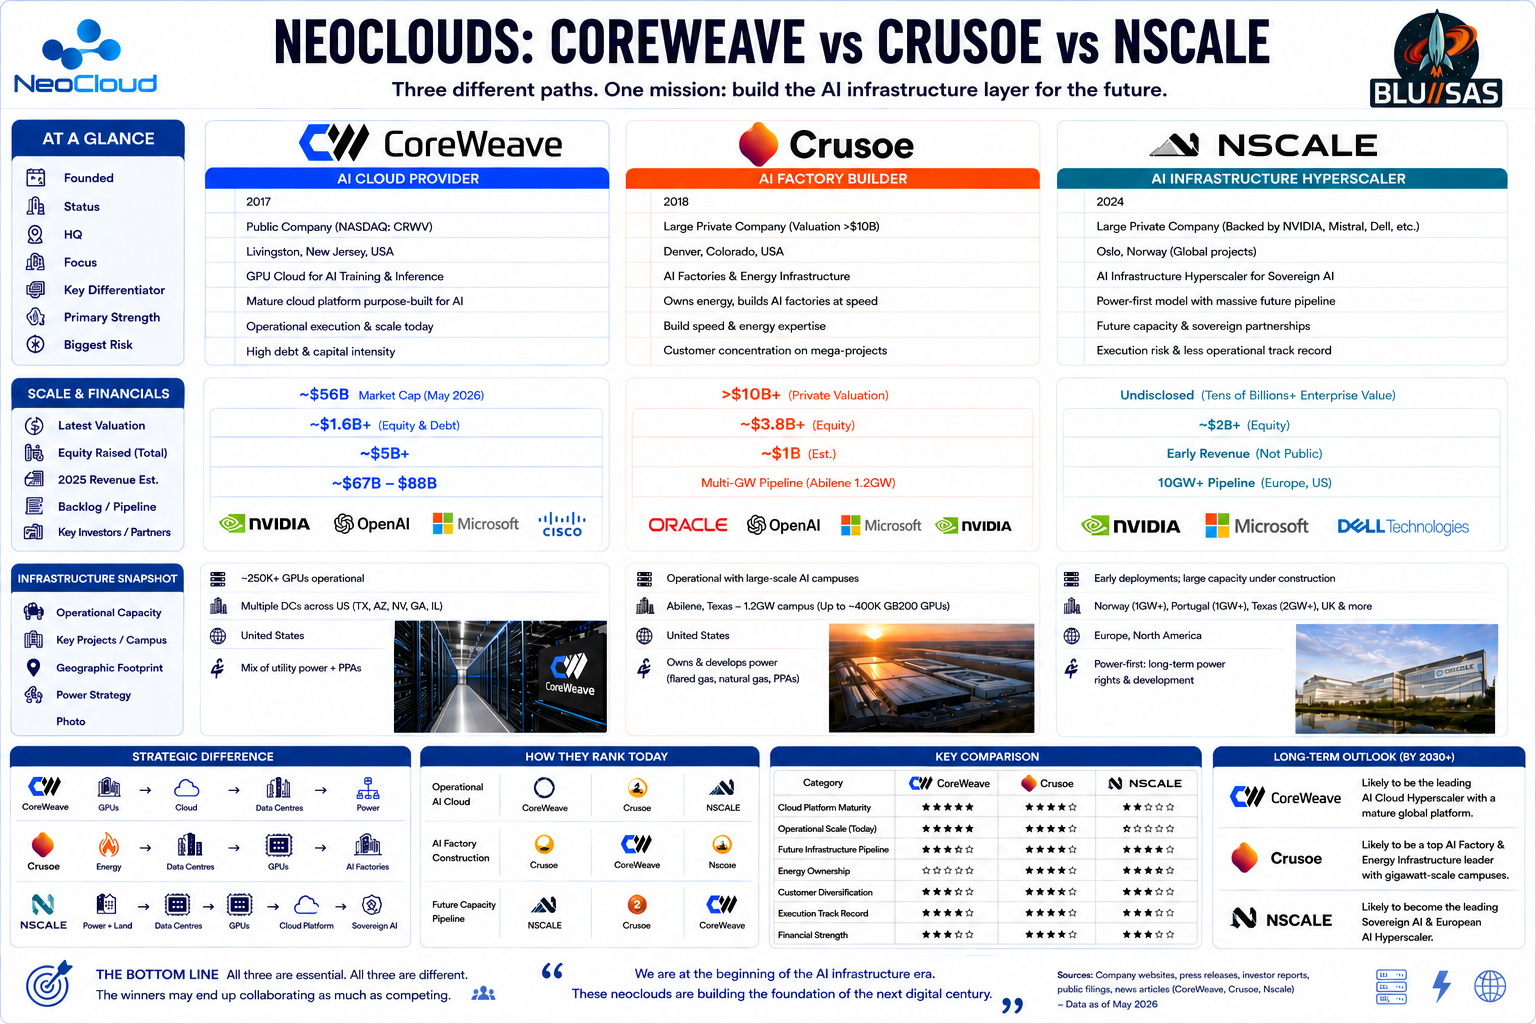
What is a Neocloud? CoreWeave, Crusoe, Nscale and Oracle vs Radiant

“Neocloud” (sometimes written neo cloud) is a term for a new generation of cloud providers that specialize in AI computing rather than offering the full range of traditional cloud services. They focus heavily on providing high-performance GPUs for AI training and inference.

How neoclouds differ from traditional cloud providers

Traditional cloud (AWS, Azure, Google Cloud)Neocloud
Broad range of services (databases, storage, networking, analytics, etc.)Primarily focused on AI and GPU computing
Designed for many types of workloadsOptimized specifically for AI/ML workloads
Large hyperscale platformsOften smaller, AI-focused companies
GPU capacity can be limited or expensiveAim to provide faster access to GPUs and lower costs

Why neoclouds became popular

The explosion of generative AI created huge demand for GPUs such as NVIDIA H100 and Blackwell chips. Many organizations struggled to obtain enough AI compute from traditional cloud providers, creating an opportunity for specialized GPU cloud companies.

Examples of neocloud providers

Some well-known neocloud companies include:

  • CoreWeave
  • Lambda
  • Crusoe
  • Nebius
  • Together AI

These companies provide GPU-as-a-Service (GPUaaS) and AI-focused infrastructure.

Simple analogy

Think of traditional cloud providers as a large supermarket that sells everything, while a neocloud is a specialty store focused almost entirely on AI computing power. It may offer fewer services overall, but it is optimized for AI workloads and often provides better access to GPUs.

Nscale a European Neocloud?

Today, a more representative list of major neoclouds would include:

CompanyRegionNotes
NscaleUK / EuropeFull-stack AI infrastructure, sovereign AI cloud, GPU cloud, data centre developer.
CoreWeaveUSOften regarded as the archetypal neocloud.
NebiusEuropeAI cloud and GPU infrastructure provider.
LambdaUSGPU cloud focused on AI training and inference.
CrusoeUSAI data centres and GPU cloud infrastructure.
Together AIUSAI platform plus infrastructure.

Nscale’s positioning is actually slightly different from some of the others because it is trying to be vertically integrated:

  • Building or owning AI data centres.
  • Procuring GPU fleets at massive scale.
  • Operating AI cloud services.
  • Offering sovereign AI infrastructure for governments and enterprises.
  • Running full-stack AI platforms rather than just renting GPUs.

Some analysts now classify Nscale as an AI hyperscaler rather than merely a neocloud because of the scale it is targeting. ABI Research ranked Nscale as the overall leader among 14 neocloud providers in its 2026 assessment.

What’s interesting is that the neocloud landscape appears to be splitting into three tiers:

  1. GPU rental companies – essentially GPU-as-a-Service.
  2. AI cloud platforms – GPUs plus AI tooling.
  3. AI hyperscalers – own data centres, networking, power, GPUs, and cloud platform.

Nscale is deliberately pursuing category 3. The company describes itself as a vertically integrated AI cloud and has announced very large-scale deployments in Europe and the US.

If you compare Nscale, CoreWeave, and Crusoe specifically, I’d place them like this:

AreaNscaleCoreWeaveCrusoe
Sovereign European AIStrongestLimitedLimited
GPU CloudStrongVery StrongStrong
Data Centre OwnershipExtensive strategyGrowingExtensive
AI Hyperscaler AmbitionVery HighHighHigh
European PresenceStrongestModerateModerate
Microsoft PartnershipsSignificantSignificantSignificant

From a European perspective, Nscale is probably the closest thing Europe currently has to a home-grown AI hyperscaler.

No. If we’re talking about Europe specifically, I would actually argue the opposite:

CoreWeave is currently ahead in deployed AI infrastructure, while Nscale is ahead in announced future European capacity.

Those are very different things.

CoreWeave’s position in Europe

CoreWeave already has:

  • European headquarters in London.
  • Two operational UK data centres.
  • Expansion into Norway, Sweden, and Spain.
  • Billions already committed and deployed into European infrastructure.
  • A mature GPU cloud platform that is already serving customers globally.

By 2025, CoreWeave had announced European expansion into Norway, Sweden, and Spain alongside its existing UK footprint.

More importantly, CoreWeave entered Europe after already becoming a large-scale AI cloud provider in the US. They brought:

  • Operational expertise
  • Existing customers
  • Existing software platform
  • Existing GPU fleet

That is a major advantage.

Where Nscale is stronger

Nscale’s strength is the future build pipeline.

Publicly announced projects include:

  • Stargate Norway
  • Sines (Portugal)
  • UK AI campus developments
  • Iceland expansion plans

Some of these projects are absolutely enormous on paper. The Norway Stargate project alone targets 100,000 NVIDIA GPUs.

Portugal is also positioned as one of Nscale’s flagship European hubs, with 12,600+ Blackwell GPUs initially and much larger Rubin deployments planned later.

The key distinction

If you compare today’s operational reality:

MetricCoreWeaveNscale
Operational GPU cloudAheadBehind
Existing customer workloadsAheadBehind
Software/cloud platform maturityAheadBehind
European operational experienceAheadBehind
Publicly visible deployed GPU capacityAheadBehind

If you compare future announced European capacity:

MetricCoreWeaveNscale
Norway buildoutLargeVery large
PortugalLimited public presenceMajor flagship site
Sovereign AI initiativesSomeStrong focus
OpenAI-linked projectsLimitedSignificant
Future European MW pipelineLargePotentially larger

A useful analogy

Today, CoreWeave is closer to:

“We already run a large AI cloud and are expanding into Europe.”

Nscale is closer to:

“We are building some of Europe’s largest AI campuses and will become a major AI cloud.”

Those are different stages of maturity.

The question investors are asking

The debate isn’t really:

“Can Nscale catch CoreWeave?”

The debate is:

“Can Nscale turn announced power, land, and GPU commitments into revenue-producing clusters before demand or financing conditions change?”

CoreWeave has already demonstrated it can operate large GPU fleets and monetize them. Nscale is in the process of proving that at the same scale.

One interesting point: some recent reporting has questioned the extent to which both companies’ European investment announcements translate into immediately operational facilities, noting that some “new data centre” claims are actually deployments into existing colocation facilities rather than brand-new campuses. That criticism has been directed at both Nscale and CoreWeave.

So as of mid-2026:

  • Operationally: CoreWeave is ahead in Europe.
  • Announced future European capacity: Nscale may have the larger headline pipeline.
  • Execution risk: Nscale has more to prove because a larger proportion of its European footprint is still future-dated.

Is Nscale’s IPO still on target for late 2026?

As of June 2026, there is no publicly filed prospectus, no announced exchange, and no confirmed IPO date for Nscale.

The strongest public indication that an IPO is still being pursued comes from industry reports stating that Nscale was planning a fall/late-2026 IPO and was pursuing additional US data-centre acquisitions ahead of that listing.

However, there are several reasons to be cautious about assuming it is “on target”:

Reasons it could still happen in late 2026

  • The AI infrastructure sector remains one of the hottest areas in public markets.
  • Investors have rewarded AI infrastructure companies such as CoreWeave since its public debut.
  • Nscale has announced very large infrastructure commitments involving Microsoft and multiple multi-hundred-megawatt campuses, which is the type of growth story public investors currently like.

Reasons it could slip into 2027

The challenge is that public-market investors increasingly want proof of:

  • Revenue growth
  • Actual GPU deployments
  • Utilization rates
  • Long-term customer contracts
  • Cash-flow visibility

rather than just power agreements and future construction plans.

Unlike CoreWeave, which entered public markets after operating large GPU fleets for years, much of Nscale’s most ambitious capacity remains future-dated. That creates execution risk that investors will scrutinize heavily.

What I would watch for

If Nscale is genuinely targeting a late-2026 IPO, I would expect to see during the next few months:

  1. Appointment of lead underwriters (Goldman Sachs, Morgan Stanley, JPMorgan, etc.).
  2. Public filing activity or confidential filing reports.
  3. More detailed revenue disclosures.
  4. Announcements of operational GPU deployments, not just planned deployments.
  5. Additional long-term customer agreements.

My assessment

If I had to assign probabilities today:

OutcomeProbability
IPO in Q4 2026~40%
IPO slips into H1 2027~45%
IPO delayed beyond 2027~15%

That’s not based on any insider information—just on where Nscale appears to be in its infrastructure rollout compared with where most AI infrastructure companies are when they ring the bell.

The most important signal is not the IPO date itself. It’s whether Nscale can demonstrate that its Norway, Texas, Portugal, and future UK capacity are being converted into revenue-generating GPU clusters with high utilization. If that evidence emerges during 2026, a late-2026 IPO becomes much more plausible.

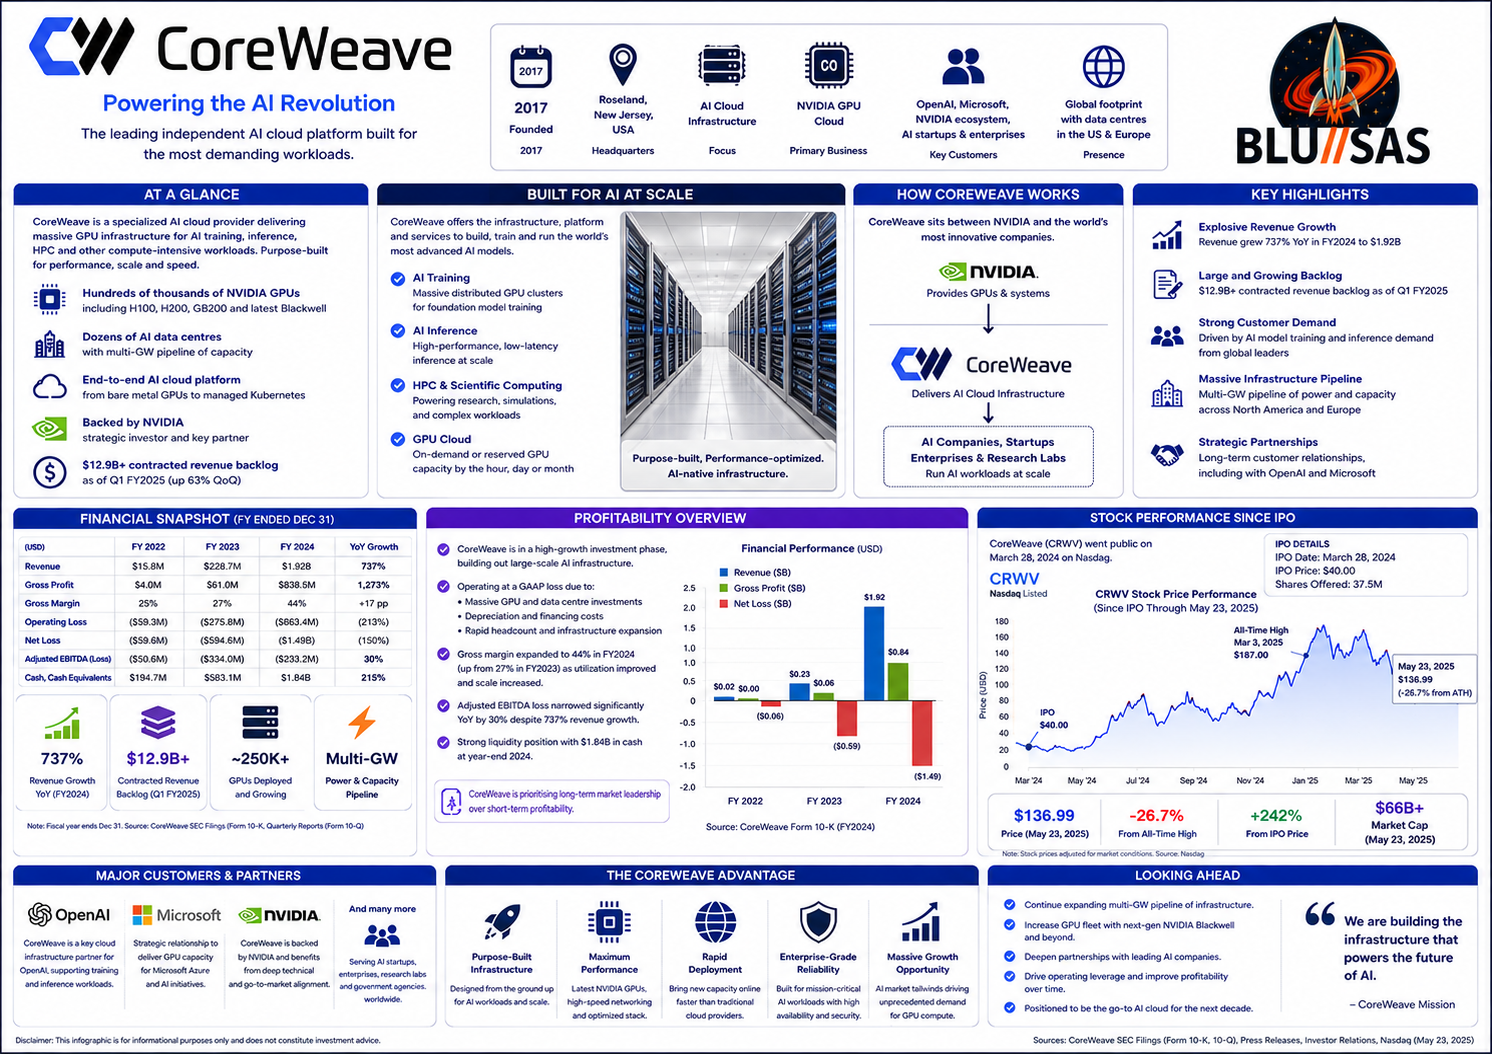
CoreWeave

CoreWeave is an AI cloud provider that specializes in delivering large-scale GPU infrastructure for AI training, inference, HPC, rendering, and scientific computing.

The company started life as a GPU-focused cloud provider and has evolved into one of the largest independent AI infrastructure companies in the world.

Unlike AWS, Azure, and Google Cloud, which offer AI as part of a broader cloud portfolio, CoreWeave is almost entirely focused on GPU-accelerated workloads.

CategoryDetails
Founded2017
HeadquartersRoseland, New Jersey, USA
FocusAI Cloud Infrastructure
Primary BusinessGPU-as-a-Service
Main CustomersOpenAI, Microsoft, NVIDIA ecosystem, AI startups
Major HardwareNVIDIA H100, H200, GB200, Blackwell
CompetitorsAWS, Azure, Google Cloud, Crusoe, Lambda, Nscale

How CoreWeave Started

The company originally operated in cryptocurrency mining.

Management realized early that:

  • GPUs used for mining
  • GPUs used for AI training
  • GPUs used for rendering

all required similar infrastructure.

When the AI boom began following the success of ChatGPT, CoreWeave pivoted aggressively into AI compute.

This turned out to be one of the best-timed pivots in the technology industry.


CoreWeave’s Business Model

Think of CoreWeave as:

NVIDIA
↓
CoreWeave
↓
AI Companies

Instead of:

NVIDIA
↓
Microsoft Azure
AWS
Google Cloud
↓
AI Companies

CoreWeave sits between NVIDIA and AI customers.


What Services Does CoreWeave Offer?

1. AI Training Clusters

Used for:

  • Large Language Models (LLMs)
  • Foundation Models
  • Multimodal Models
  • Scientific AI

Examples:

  • GPT-style models
  • Image generation models
  • Robotics models

Typical infrastructure:

  • Thousands of GPUs
  • InfiniBand networking
  • Petabytes of storage

2. AI Inference

After a model is trained:

Training
↓
Model
↓
Inference

Inference is what happens when:

  • You ask ChatGPT a question
  • Generate an image
  • Run a chatbot

CoreWeave provides infrastructure for this at scale.


3. HPC

High Performance Computing workloads:

  • Weather modelling
  • Genomics
  • Drug discovery
  • CFD
  • Physics simulations

This is an area where CoreWeave competes with traditional HPC centres.


4. GPU Cloud

Instead of buying:

  • H100s
  • H200s
  • Blackwell systems

Customers rent them by:

  • Hour
  • Day
  • Month

Why NVIDIA Likes CoreWeave

NVIDIA has invested in CoreWeave because CoreWeave helps NVIDIA:

  • Deploy GPUs faster
  • Reach AI startups
  • Increase GPU utilization
  • Expand GPU cloud capacity

NVIDIA has been both a supplier and investor.


CoreWeave Infrastructure

Typical CoreWeave clusters contain:

NVIDIA GPUs
│
InfiniBand
│
GPU Nodes
│
High-speed Storage
│
Kubernetes
│
Customer Workloads

Technologies typically include:

  • NVIDIA DGX
  • HGX
  • InfiniBand
  • RoCE
  • Kubernetes
  • Slurm
  • Object Storage

How Big is CoreWeave?

By 2026, CoreWeave is operating or building infrastructure measured in:

  • Hundreds of thousands of GPUs
  • Multiple gigawatts of power
  • Dozens of AI data centres

This puts them among the largest AI-focused cloud providers globally.


Why Microsoft Matters

One of CoreWeave’s biggest customers has been Microsoft.

Microsoft has used CoreWeave capacity to supplement Azure AI infrastructure when Azure could not provision GPUs quickly enough.

This relationship helped accelerate CoreWeave’s growth enormously.


CoreWeave vs Nscale

AreaCoreWeaveNscale
Founded20172024
StageMature AI cloudEmerging AI hyperscaler
GPUs Deployed TodayVery LargeMore Limited
RevenueMuch HigherEarlier Growth
Operational ExperienceExtensiveBuilding
US PresenceMajorGrowing
Europe PresenceGrowingLarge Future Pipeline
Data CentresOperating TodayMany Future Builds
AI Cloud PlatformMatureDeveloping

What Would Interest an SRE?

For someone coming from:

  • Kubernetes
  • Observability
  • OpenTelemetry
  • Prometheus
  • Mimir
  • Loki
  • Tempo
  • HPC

CoreWeave is fascinating because it combines:

Infrastructure Scale

Thousands of servers per cluster.

AI Networking

  • InfiniBand
  • RoCE
  • GPUDirect RDMA

Storage

  • High-throughput parallel storage
  • Object storage
  • Checkpointing

Reliability

When a training run consumes:

10,000 GPUs
×
7 days

a single infrastructure failure can cost millions of dollars.

This creates unique SRE challenges around:

  • Cluster reliability
  • GPU scheduling
  • Capacity management
  • Fleet automation
  • Telemetry at hyperscale
  • AI workload observability

Why CoreWeave is Important

CoreWeave is one of the first companies to prove that a specialist AI cloud provider can compete with traditional hyperscalers.

The company effectively created a new category:

Traditional Cloud
AWS
Azure
GCP

vs

AI Cloud
CoreWeave
Crusoe
Lambda
Nscale

That category is now one of the fastest-growing areas of infrastructure technology and is driving much of the current AI infrastructure build-out worldwide.

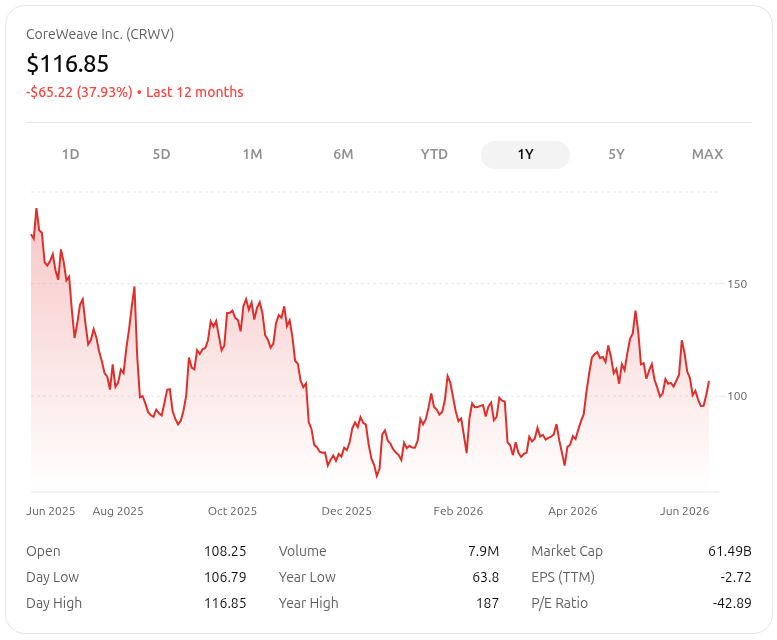
CoreWeave’s stock has had one of the most volatile post-IPO journeys in the AI infrastructure sector.

Share Price Since IPO

CoreWeave completed its Nasdaq IPO in March 2025 under the ticker CRWV. The IPO was downsized before launch, raising about $1.5 billion rather than the larger amount initially targeted.

The broad trajectory has been:

PeriodApproximate Story
Mar 2025 IPOWeak initial reception and downsized offering
Apr–Jun 2025Strong AI enthusiasm drove shares sharply higher
Jun 2025Reached all-time highs around $187/share
H2 2025Significant correction as investors focused on debt, losses, and data-centre execution
Early 2026Recovery driven by AI demand, Anthropic, Meta, OpenAI and enterprise growth
Jun 2026Trading around $107/share

Recent trading puts the company at a market capitalization of roughly $56 billion.


The Good News Financially

Revenue Growth Is Extraordinary

CoreWeave is one of the fastest-growing infrastructure companies in the market.

Examples include:

  • Revenue more than doubled year-over-year in multiple recent quarters.
  • Enterprise adoption is expanding beyond AI labs into financial services and large enterprises.
  • Revenue backlog reached approximately $99.4 billion as of Q1 2026.

That backlog is enormous and provides strong visibility into future revenue.


Major Customers

CoreWeave has secured relationships with:

These are arguably the most important AI infrastructure customers on the planet.


Scale Advantage

Reuters recently noted that CoreWeave has:

  • More than 1 GW already deployed
  • More than 3.5 GW contracted for future deployment

This places it among the largest dedicated AI infrastructure operators globally.


The Risks

Massive Debt Load

This is the biggest concern.

CoreWeave financed much of its growth through:

  • Asset-backed debt
  • Infrastructure loans
  • GPU-backed financing
  • Convertible notes

Multiple analysts and investors have pointed to the company’s very large debt burden as its primary financial risk.

The business model requires spending billions before revenue arrives.


Still Losing Money

Despite explosive revenue growth, CoreWeave remains unprofitable on a net-income basis.

Investors are essentially betting that:

Revenue Growth
>
Interest Costs + Depreciation + Expansion Costs

over the long term.

Recent earnings showed revenue beating expectations while margins and profitability remained under pressure.


Customer Concentration

Historically, a large portion of revenue has come from a relatively small number of customers.

If:

  • OpenAI
  • Microsoft
  • Meta
  • Anthropic

decide to build more capacity themselves, future growth could be affected.

This is one reason investors closely watch customer mix and backlog growth.


Why Investors Still Like It

The bullish thesis is straightforward:

  1. AI demand continues growing.
  2. GPU supply remains constrained.
  3. Training and inference workloads keep increasing.
  4. CoreWeave owns and operates the infrastructure needed to satisfy that demand.

In that scenario, today’s debt becomes manageable because revenue grows faster than financing costs.


Compared with Nscale

If I compare the two today:

AreaCoreWeaveNscale
Public CompanyYesNot yet
Market Cap~$56BPrivate
RevenueMulti-billionMuch smaller
Operational GPU CapacityVery largeLimited publicly visible
Revenue Backlog~$99BNot publicly disclosed at same level
DebtVery highMuch lower today
Execution RiskModerateHigh
Infrastructure MaturityEstablishedEmerging

CoreWeave’s biggest challenge is financial leverage.

Nscale’s biggest challenge is execution.

CoreWeave has already proven it can build and operate AI infrastructure at scale. The question investors are asking is whether it can generate enough cash flow to justify the enormous capital expenditure and debt required to stay ahead in the AI compute race.

Crusoe

Crusoe is arguably the third major AI infrastructure challenger behind CoreWeave and the large hyperscalers, and alongside Nscale and Radiant in the race to build AI factories.

What makes Crusoe unique is that it evolved from an energy company into an AI infrastructure company.

Its progression has been roughly:

Flared Gas Capture
↓
Power Generation
↓
Bitcoin Mining
↓
GPU Infrastructure
↓
AI Cloud
↓
AI Factories

Today the company describes itself as an “AI Factory Company” rather than a traditional cloud provider.


Current Position

Valuation

Crusoe raised:

  • $600M Series D (2024)
  • $1.375B Series E (2025)

at a valuation exceeding $10 billion.

There are also industry reports suggesting private-market discussions at significantly higher valuations during 2026, though these are not official company figures.


Funding Strength

Crusoe has now raised approximately:

  • $3.8B+ equity funding
  • Additional billions in project finance and credit facilities

including a $750M Brookfield-backed credit facility.

Compared with many startups, Crusoe has become exceptionally well capitalized.


The Abilene AI Campus

The company’s flagship project is:

Abilene, Texas

This has become one of the largest AI infrastructure projects in the world.

Public reports describe:

  • 1.2 GW campus
  • Up to ~400,000 NVIDIA GB200-class GPUs planned
  • $15B+ joint venture funding
  • Major Oracle/OpenAI involvement
  • Multiple operational buildings already online

This campus is one of the key foundations of the Stargate ecosystem.


Relationship With OpenAI, Oracle & Microsoft

Crusoe sits at the center of a fascinating triangle:

OpenAI
│
Oracle
│
Crusoe
│
Microsoft

Recent developments have been mixed:

Positive

Oracle states:

  • Abilene remains on schedule
  • Two buildings are operational
  • Additional Stargate capacity remains under development

Complicated

Several planned expansions have changed tenants or scope.

Reports indicate:

  • OpenAI and Oracle stepped back from some expansion plans.
  • Microsoft subsequently agreed to lease part of the adjacent capacity.
  • Meta has reportedly evaluated some available capacity.

This isn’t necessarily bad news—it may actually demonstrate that demand is broad enough that multiple hyperscalers are competing for capacity.


Revenue Performance

Industry estimates suggest:

YearRevenue
2024~$276M
2025~$998M
2026Potentially >$2B

These are not audited public-company figures but are widely cited estimates reflecting the company’s rapid growth trajectory.

If accurate, Crusoe would be among the fastest-growing infrastructure companies globally.


Why Investors Like Crusoe

1. Speed

Crusoe has developed a reputation for building AI infrastructure extremely quickly.

Some investors explicitly cite build speed as a competitive advantage versus traditional data-center developers.


2. Vertical Integration

Unlike many competitors, Crusoe controls:

Power
↓
Generation
↓
Infrastructure
↓
Data Centres
↓
GPU Cloud

This resembles Radiant’s strategy and increasingly resembles Nscale’s.


3. AI Factory Focus

The company is moving beyond:

GPU Rental

toward:

Complete AI Factories

which is where the largest contracts are emerging.


Current Challenges

1. Customer Concentration

Much of Crusoe’s growth is tied to:

  • OpenAI
  • Oracle
  • Microsoft

This creates concentration risk.

If one customer changes strategy, large projects can be affected.


2. Capital Intensity

Like CoreWeave, Crusoe requires enormous capital expenditures.

Building:

  • Multi-GW campuses
  • Power infrastructure
  • GPU fleets

requires tens of billions of dollars.


3. Project Volatility

Recent examples include:

  • Wyoming project pause
  • Changing Stargate scope
  • Customer reallocations between OpenAI, Oracle, Microsoft and others

This demonstrates that even the hottest AI infrastructure projects are not immune to execution risk.


How Crusoe Compares

CategoryCoreWeaveCrusoeNscaleRadiant
Public CompanyYesNoNoNo
Valuation~$56B market cap$10B+ privatePrivatePrivate
AI Cloud PlatformMatureGrowing rapidlyEmergingOri platform
Operational AI InfrastructureVery largeLargeSmaller todayEarly
AI Factory FocusStrongVery strongVery strongVery strong
Energy IntegrationModerateStrongStrongExceptional
IPO CandidateAlready publicLikely future IPOPotential IPOLong-term possibility

What I Think of Crusoe

Among the “new hyperscalers”:

  1. CoreWeave is currently the operational leader.
  2. Crusoe is probably the most advanced private AI infrastructure company.
  3. Nscale has one of the largest future pipelines.
  4. Radiant may have the strongest long-term capital structure because of Brookfield.

Crusoe’s biggest strength is that it has already proven it can deliver and operate very large AI campuses while still retaining startup-level speed. Its biggest challenge is moving from a few gigantic flagship projects into a diversified, repeatable AI infrastructure business that is less dependent on any single customer or project.

CoreWeave vs Crusoe vs Nscale

These are arguably the three most important “Neoclouds” today.

All three are trying to become the AI-era equivalent of hyperscalers, but they are taking very different paths.

Executive Summary

CompanyCoreWeaveCrusoeNscale
Founded201720182024
StatusPublic companyLarge private companyLarge private company
Core IdentityAI cloud providerAI factory builderAI infrastructure hyperscaler
Geographic StrengthUSUSEurope
Operational MaturityHighestHighEmerging
AI Cloud PlatformMost matureGrowingDeveloping
Energy OwnershipLimitedStrongStrong
Future Capacity PipelineLargeVery LargeEnormous
Biggest RiskDebtCustomer concentrationExecution
Biggest StrengthOperational excellenceInfrastructure deliveryPower + future capacity

CoreWeave is currently winning on execution. Crusoe is winning on AI factory construction. Nscale is winning on future infrastructure ambition.


1. CoreWeave

What CoreWeave Is

CoreWeave is fundamentally an AI-native cloud provider.

Think:

AWS for GPUs

except purpose-built for:

  • AI training
  • AI inference
  • LLMs
  • HPC

Its cloud platform is already mature and heavily used by large AI companies. CoreWeave operates dozens of data centres, hundreds of thousands of GPUs, and has become one of NVIDIA’s most important cloud partners.

Strengths

  • Most mature software platform
  • Largest operational fleet
  • Strong OpenAI, Microsoft, Meta, Anthropic relationships
  • Fastest revenue growth
  • Proven ability to monetize GPUs

CoreWeave reported more than $5B revenue and a backlog approaching $67B-$88B depending on reporting period.

Weaknesses

  • Huge debt load
  • Heavy capex requirements
  • Customer concentration
  • Public market scrutiny

2. Crusoe

What Crusoe Is

Crusoe is best described as:

Energy Company
+
AI Factory Builder
+
GPU Cloud

It started by monetizing stranded energy and evolved into building some of the largest AI campuses in the world.

The Abilene campus in Texas has become one of the flagship AI infrastructure projects globally and is tied to Oracle and OpenAI’s broader Stargate ecosystem.

Strengths

  • Extremely fast construction capability
  • Strong energy expertise
  • Large-scale AI factory delivery
  • Deep OpenAI/Oracle ecosystem integration

Weaknesses

  • Smaller cloud platform than CoreWeave
  • Less diversified customer base
  • Still heavily tied to a few mega-projects

What Crusoe Wants To Become

Crusoe appears to be evolving toward:

AI Factory Company

rather than simply a GPU cloud.


3. Nscale

What Nscale Is

Nscale is pursuing the most ambitious infrastructure vision.

Their strategy is:

Power
↓
Land
↓
Data Centres
↓
GPUs
↓
Cloud Platform

They are effectively trying to build a European AI hyperscaler from scratch.

Strengths

  • Massive future pipeline
  • Strong sovereign AI positioning
  • European leadership position
  • Large power commitments
  • Strong Microsoft/OpenAI/NVIDIA relationships

Weaknesses

  • Much of capacity remains future-dated
  • Less operational experience
  • Less mature cloud platform
  • Execution risk

Public reporting has highlighted that several headline projects remain in buildout or planning phases rather than being fully operational today.


The Strategic Difference

CoreWeave

Started with:

GPUs

Then added:

Cloud
→ Data Centres
→ Power

Crusoe

Started with:

Energy

Then added:

Data Centres
→ GPUs
→ AI Factories

Nscale

Started with:

Power + Infrastructure

Then added:

GPUs
→ Cloud
→ Sovereign AI

Which Company Is Furthest Ahead Today?

Operational AI Cloud

Winner:

🥇 CoreWeave

Reason:

  • Largest operational fleet
  • Most mature software platform
  • Largest customer base

AI Factory Construction

Winner:

🥇 Crusoe

Reason:

  • Abilene
  • Stargate involvement
  • Proven delivery capability

Future Capacity Pipeline

Winner:

🥇 Nscale

Reason:

  • Norway
  • Portugal
  • Texas
  • UK projects
  • Sovereign AI initiatives

Which Is Closest To Becoming a New Hyperscaler?

Today

CoreWeave
↑
|
Crusoe
|
Nscale

By 2030 (Potential)

CoreWeave
Crusoe
Nscale

All three could be major AI infrastructure providers, but they will likely specialize differently:

CompanyLikely Long-Term Identity
CoreWeaveAI Cloud Hyperscaler
CrusoeAI Factory & Energy Infrastructure Leader
NscaleSovereign AI & European AI Hyperscaler

From an SRE / Cloud Infrastructure Perspective

If you wanted to work on the most technically mature environment today:

CoreWeave

If you wanted to build some of the world’s largest AI campuses:

Crusoe

If you wanted to help create a new AI hyperscaler from the ground up:

Nscale

That is the clearest distinction between the three companies as of mid-2026.

Who is Radiant?

Radiant/Ori is one of the more interesting challengers because they are not trying to copy CoreWeave or Nscale exactly.

Instead, they are attempting to combine:

  • Brookfield’s enormous infrastructure and energy assets
  • Ori’s AI cloud software platform
  • NVIDIA’s AI factory ecosystem
  • Sovereign AI demand from governments and large enterprises

into a vertically integrated AI infrastructure company.

What is Ori?

Before the merger, Ori Industries was a UK AI cloud company founded in 2019.

Ori built:

  • Distributed GPU cloud infrastructure
  • AI model training platforms
  • AI deployment services
  • Multi-location AI compute services

The company operated AI infrastructure across more than 20 global locations and developed software to orchestrate AI workloads across GPU infrastructure.

Think of Ori as:

What CoreWeave built:
GPU Cloud Platform

What Ori built:
Distributed AI Infrastructure Platform

Ori’s technology is arguably the key intellectual property in the merger.


What is Radiant?

Radiant is Brookfield’s AI infrastructure company.

Brookfield is one of the world’s largest infrastructure investors with hundreds of billions under management spanning:

  • Power generation
  • Transmission
  • Renewable energy
  • Real estate
  • Data centres
  • Infrastructure projects

Radiant was created to become Brookfield’s AI compute platform.


Why Brookfield Matters

This is where Radiant becomes potentially disruptive.

Most AI clouds have a structure like:

Raise Venture Capital
↓
Buy GPUs
↓
Rent Datacentre Space
↓
Sell Compute

CoreWeave largely grew this way.

Nscale is evolving toward:

Power
↓
Datacentres
↓
GPUs
↓
Cloud Platform

Radiant starts with:

Brookfield Capital
+
Brookfield Power
+
Brookfield Land
+
Brookfield Datacentres
+
Ori Software

That means they potentially have access to cheaper capital than most AI startups.


Their Stated Strategy

Radiant has publicly described itself as a vertically integrated AI infrastructure platform.

Target customers include:

  • Sovereign governments
  • Hyperscalers
  • Tier-1 telecom operators
  • Large enterprises

Rather than simply renting GPUs to startups.

Their focus appears to be:

AI Factories

Large installations of:

  • NVIDIA GPUs
  • AI networking
  • AI storage
  • AI orchestration software

built for nations and large corporations.


The NVIDIA Connection

Radiant is built around NVIDIA’s AI factory vision.

Public statements indicate:

  • NVIDIA contributed capital to Brookfield’s AI fund.
  • NVIDIA will supply GPUs.
  • Radiant will deploy NVIDIA DSX AI factories.

This places them squarely in the same ecosystem as:

  • CoreWeave
  • Crusoe
  • Lambda
  • Nscale

but with a heavier focus on sovereign infrastructure.


How They Intend to Join the Hyperscaler Club

The strategy appears to be:

Phase 1: Acquire Software

Acquire Ori.

Result:

GPU Cloud Software
AI Orchestration
AI Platform Expertise

✓ Completed.


Phase 2: Leverage Brookfield Infrastructure

Use Brookfield’s:

  • powered land
  • data centres
  • energy assets

instead of building everything from scratch.

This is a major advantage versus startups.


Phase 3: Build Sovereign AI Factories

Target:

  • governments
  • national AI initiatives
  • regulated industries

This aligns well with Europe’s push toward sovereign AI and AI factories.


Phase 4: Scale Like a Utility

This is probably the most important difference.

Several executives have stated they want AI infrastructure financed like:

Power Stations
Utilities
Rail Networks
Airports

rather than venture-backed cloud startups.

That could significantly lower financing costs compared with many GPU cloud providers.


How Do They Compare?

CompanyCoreWeaveNscaleRadiant
Founded201720242026
PublicYesNoNo
Core StrengthOperating GPU cloudsBuilding AI campusesInfrastructure + software
Main BackerPublic marketsInvestors/NVIDIABrookfield
FocusAI cloudAI hyperscalerAI utility model
Sovereign AIModerateStrongVery Strong
Capital AccessGoodGoodPotentially Exceptional
Operational GPU Scale TodayHighestLowerVery Early

What Could Make Radiant Dangerous?

If you look at this as an SRE or infrastructure engineer, the biggest threat to competitors is not technology.

It is cost of capital.

CoreWeave’s biggest weakness is debt.

Nscale’s biggest challenge is execution.

Radiant’s pitch is:

“We already own the power, land, infrastructure financing, and data-centre expertise. We just needed the AI cloud software.”

That is precisely what the Ori acquisition gives them.

If Brookfield genuinely deploys the AI Infrastructure Fund at the scale discussed publicly (up to $10B fund commitments and potentially much larger through co-investment structures), Radiant could become one of the few companies capable of competing with CoreWeave, Nscale, Crusoe, and the hyperscalers in the sovereign AI factory market.

For someone with a background in Kubernetes, OpenStack, HPC, AI infrastructure, observability, Ceph, Slurm, and GPU platforms, Radiant is arguably one of the most interesting companies to watch over the next 2–3 years because they are trying to build the “AI utility company” rather than just another GPU cloud.

Is Radiant Ramping Up Recruitment?

If I were advising Radiant’s leadership after the Brookfield + Ori merger, I would not primarily hire more software developers or more data-centre staff initially.

The biggest challenge is integrating:

Energy Infrastructure
+
Data Centres
+
GPU Factories
+
Cloud Platform
+
Sovereign AI

into a single operating model.

That requires a very specific set of engineers.


Tier 1 — Recruit Immediately

These are the highest-priority hires.

1. Principal AI Infrastructure Architects

Need 5–10 globally.

Background:

  • CoreWeave
  • Microsoft Azure
  • AWS
  • Google
  • Oracle Cloud
  • NVIDIA
  • Crusoe
  • Nscale

Skills:

  • AI factories
  • Multi-GW campuses
  • GPU fabrics
  • Infrastructure strategy

These people define the architecture.

Without them everyone builds different solutions.


2. Staff/Principal GPU Platform Engineers

Need 20–50.

Skills:

  • Kubernetes
  • GPU Operator
  • Slurm
  • CUDA
  • MIG
  • NCCL
  • DGX/HGX

Responsibilities:

GPU lifecycle
GPU scheduling
GPU utilization
GPU observability

These are the people that actually make expensive GPUs productive.


3. Staff Network Engineers

Need 20–40.

The AI industry is becoming:

Network Limited
rather than
GPU Limited

Experience:

  • InfiniBand
  • RoCE
  • EVPN/VXLAN
  • Arista
  • NVIDIA Spectrum
  • Mellanox

Sources:

  • Meta
  • Microsoft
  • NVIDIA
  • Oracle OCI
  • Azure

4. Site Reliability Engineers

Need 30–60.

Not generic web SREs.

Need:

  • Kubernetes
  • Linux
  • GPU clusters
  • Storage
  • Automation

Focus:

Reliability
Capacity
Performance
Automation

5. Observability Platform Engineers

Need 10–20.

This is where many AI companies are currently weak.

Technology:

  • OpenTelemetry
  • Prometheus
  • Mimir
  • Loki
  • Tempo
  • ClickHouse
  • Kafka

Mission:

Observe
Everything

including:

  • GPUs
  • Power
  • Cooling
  • Storage
  • Training jobs
  • Networks

This is one of the areas where someone with your background would be valuable.


Tier 2 — Build During Year One

6. OpenStack Engineers

Many sovereign customers still want:

Private Cloud

rather than:

Public GPU Cloud

Need:

  • Nova
  • Neutron
  • Cinder
  • Ironic

Especially for government customers.


7. Storage Engineers

Need 15–30.

Experience:

  • Ceph
  • Lustre
  • BeeGFS
  • Weka
  • VAST

AI clusters consume storage at enormous scale.


8. Infrastructure Software Engineers

Need 20–50.

Build:

  • Fleet management
  • Provisioning
  • Capacity systems
  • Internal developer platforms

Languages:

  • Go
  • Python
  • Rust

9. Platform Security Engineers

Need 10–20.

Focus:

  • Supply chain security
  • GPU isolation
  • Sovereign compliance
  • Zero trust

Tier 3 — The Secret Weapon

These are the hires that separate a cloud provider from an AI hyperscaler.

10. HPC Engineers

Need 20–40.

Backgrounds:

  • National labs
  • Universities
  • Supercomputing centres

Skills:

  • Slurm
  • MPI
  • InfiniBand
  • Parallel filesystems

These people understand:

10,000 GPU training jobs

better than most cloud engineers.


11. Power Systems Engineers

This is where Brookfield can dominate.

Need:

  • Utility engineers
  • Grid engineers
  • High-voltage engineers

Most AI companies have very few.

Brookfield already has many.

Radiant should integrate them directly.


12. Cooling Engineers

Future AI factories may be:

100MW+
500MW+
1GW+

Cooling becomes strategic.

Need expertise in:

  • Liquid cooling
  • Direct-to-chip
  • Immersion

The Leadership Layer

Radiant’s biggest risk is organizational silos.

Avoid:

Brookfield Team
|
|
Ori Team

Instead build:

AI Infrastructure
|
+-- Energy
+-- Datacentres
+-- GPU Platform
+-- SRE
+-- Observability
+-- Security

If I Had £100M Hiring Budget

I’d prioritize:

RoleApprox Headcount
GPU Platform Engineers40
SREs40
Network Engineers30
Infrastructure Software Engineers30
Storage Engineers20
Observability Engineers15
HPC Engineers20
Security Engineers15
AI Infrastructure Architects10
Power/Cooling Specialists20

Total: ~240 specialist engineers.


The Three Most Valuable Hires

If Radiant could only hire three categories tomorrow:

  1. Principal GPU Platform Engineers
  2. Principal AI Networking Engineers
  3. Principal Observability/SRE Engineers

Those three groups determine whether a 100,000-GPU AI factory operates at:

95% utilization

or

60% utilization

The difference is potentially hundreds of millions of dollars per year in infrastructure efficiency. For a company trying to become an AI utility, those engineering disciplines are arguably more important than almost any other technical hiring category.

Oracle’s Journey

Phase 1: Database Company (1977-2010)

For decades Oracle was essentially:

Databases
+
Enterprise Software

Revenue came from:

  • Oracle Database
  • Enterprise applications
  • Middleware
  • Support contracts

Oracle dominated enterprise IT but missed the early public cloud wave.


Phase 2: Late Cloud Entrant (2010-2020)

AWS, Azure and Google Cloud were already well established.

Oracle’s first cloud attempts struggled because they largely tried to:

Move Oracle Products
↓
Into Oracle Cloud

rather than building a cloud-native platform.

OCI v1 wasn’t competitive.


Phase 3: OCI Rebuild (2018-2024)

This is where Oracle changed direction.

Under Clay Magouyrk’s leadership, OCI was essentially rebuilt from scratch.

Key design decisions:

Bare Metal First

Unlike AWS:

Physical Server
↓
Hypervisor
↓
VM

OCI emphasized:

Physical Server
↓
Customer

This became attractive for:

  • HPC
  • AI
  • Databases

RDMA Networking

Oracle invested heavily in:

  • RoCE
  • RDMA
  • HPC fabrics

Years before AI made these mainstream.

This is one reason OCI became attractive for GPU clusters.


Autonomous Infrastructure

OCI automated large parts of:

  • provisioning
  • patching
  • operations

allowing Oracle to run cloud regions with fewer people.


Phase 4: AI Pivot (2023-Present)

ChatGPT changed everything.

Oracle suddenly found that:

Their Strengths Were AI Strengths

They already had:

✓ Bare metal

✓ HPC networking

✓ RDMA

✓ Large data centres

✓ Enterprise customers

These are exactly what AI workloads need.


The OpenAI Relationship

This is where Oracle became a serious AI player.

Oracle started providing infrastructure for:

  • OpenAI
  • Microsoft
  • Stargate

through extremely large GPU deployments.

Oracle is now one of the biggest buyers of NVIDIA GPUs in the world.


Oracle’s AI Infrastructure Today

Oracle is building:

GB200 Clusters

Blackwell Clusters

RoCE Fabrics

AI Superclusters

At a scale that rivals many neoclouds.

Some deployments involve:

10,000+
50,000+
100,000+ GPUs

depending on project.


Why Oracle Is Different From CoreWeave

CoreWeave started with:

GPUs
↓
Cloud

Oracle started with:

Cloud
↓
GPUs

This gives Oracle advantages.


Existing Customers

Oracle already has:

  • banks
  • governments
  • telecoms
  • healthcare

These customers are now buying AI services.

CoreWeave must acquire those customers.

Oracle already has them.


Existing Revenue

Oracle generates tens of billions annually.

This means they can fund AI expansion from operating cash flow.

CoreWeave relies more heavily on:

  • debt
  • equity
  • project financing

Existing Global Footprint

OCI already operates dozens of regions.

Nscale and Crusoe are still building much of theirs.


Is Oracle Becoming a Hyperscaler?

Oracle already is one.

OCI is generally considered the fourth major hyperscaler after:

  1. AWS
  2. Azure
  3. Google
  4. Oracle

The question is really:

Is Oracle becoming an AI hyperscaler?

The answer is:

Yes.


Is Oracle Becoming a Neocloud?

Not really.

Neoclouds are generally:

AI First

Examples:

  • CoreWeave
  • Crusoe
  • Nscale
  • Radiant

Oracle is:

Cloud First
↓
AI Enhanced

A different origin story.


What Oracle Is Morphing Into

I would describe Oracle as:

Traditional Hyperscaler
+
AI Factory Operator
+
GPU Supercluster Provider

In fact Oracle increasingly resembles:

AWS + CoreWeave

combined.

AWS scale.

CoreWeave-style GPU infrastructure.


Why This Matters for the AI Race

The biggest threat to CoreWeave, Nscale and Crusoe may not be each other.

It may be Oracle.

Because Oracle has:

✓ Existing cloud

✓ Existing customers

✓ Existing revenue

✓ Existing data centres

✓ Existing support organisation

✓ Existing enterprise sales force

✓ Massive GPU procurement

The neoclouds must build these capabilities.

Oracle already has them.


The Next 5 Years

If current trends continue:

CompanyLikely Position 2030
AWSLargest general cloud
AzureLargest enterprise AI cloud
GoogleAI + data platform leader
OracleAI infrastructure hyperscaler
CoreWeaveLargest independent AI cloud
CrusoeAI factory leader
NscaleSovereign AI hyperscaler
RadiantAI utility platform

My view is that Oracle is not becoming a neocloud.

Instead, Oracle is doing something arguably more powerful:

It is transforming from a traditional hyperscaler into an AI hyperscaler while retaining all the advantages of an established cloud provider.

That combination of existing scale, enterprise relationships, and AI infrastructure investment is why Oracle has suddenly become one of the most important players in the AI infrastructure market.

Is Oracle the opposite of Radiant and vice versa?

Not exactly, but they are surprisingly close to being mirror images of each other.

If you look at their origins:

OracleRadiant
Started with softwareStarted with infrastructure
Database companyInfrastructure company
Built cloud platformAcquired cloud platform (Ori)
Added AI laterAdded AI from day one
Enterprise customers firstSovereign AI first
Compute-centricPower-centric
Cloud → AIInfrastructure → AI

A useful way to think about it is:

Oracle
-------
Software
↓
Database
↓
Cloud
↓
AI Infrastructure

Radiant
--------
Infrastructure
↓
Power
↓
Data Centres
↓
AI Infrastructure

So they are converging on a similar destination from opposite directions.


Oracle’s DNA

Oracle fundamentally thinks like a software company.

Its worldview is:

Application
↓
Database
↓
Cloud Platform
↓
Infrastructure

Its biggest assets are:

  • Enterprise customers
  • Databases
  • SaaS products
  • Sales organisation
  • OCI platform

AI is an extension of those assets.

Oracle asks:

“How do we deliver AI to our existing customers?”


Radiant’s DNA

Radiant fundamentally thinks like an infrastructure company.

Its worldview is:

Power
↓
Land
↓
Data Centre
↓
GPU Factory
↓
AI Services

Its biggest assets are:

  • Brookfield capital
  • Brookfield power
  • Brookfield real estate
  • Brookfield infrastructure expertise
  • Ori’s AI platform

Radiant asks:

“How do we build the infrastructure that powers AI?”


The Biggest Difference

Oracle’s bottleneck is usually:

Customer Demand

They already have:

  • Data centres
  • Customers
  • Revenue

They need more GPUs and power.


Radiant’s bottleneck is usually:

Software & Customer Acquisition

They already have:

  • Capital
  • Infrastructure expertise
  • Energy

They need:

  • AI cloud adoption
  • Enterprise relationships
  • Platform scale

What They Are Trying To Become

Oracle is evolving toward:

AI Hyperscaler

Radiant is evolving toward:

AI Utility

Those are related but different.

Oracle Vision

Oracle Cloud
+
AI Superclusters
+
Enterprise AI

Think:

“AWS/Azure with massive AI capability.”


Radiant Vision

Power
+
Data Centres
+
AI Factories
+
Long-term Infrastructure Contracts

Think:

“National Grid meets CoreWeave.”


Why Radiant Could Learn From Oracle

Radiant lacks:

  • Enterprise software experience
  • Large-scale customer operations
  • Decades of cloud platform evolution

Oracle has all of that.


Why Oracle Could Learn From Radiant

Radiant understands:

  • Power economics
  • Infrastructure financing
  • Long-duration capital
  • Utility-scale thinking

areas where Oracle historically has less expertise.


If They Met In The Middle

The interesting thing is that both companies are converging toward something like:

Power
↓
Data Centre
↓
GPU Factory
↓
Cloud Platform
↓
Enterprise AI

The difference is where they started.

LayerOracle StrengthRadiant Strength
PowerModerateExceptional
Data CentresStrongExceptional
GPUsStrongEmerging
Cloud PlatformExceptionalGood (via Ori)
Enterprise SalesExceptionalDeveloping
Sovereign AIModerateStrong
Long-Term Infrastructure FinanceModerateExceptional

The More Interesting Comparison

I actually think the closest opposite of Radiant is not Oracle.

It’s CoreWeave.

CoreWeave

Started with:

GPUs
↓
Cloud
↓
Data Centres
↓
Power

Radiant

Started with:

Power
↓
Data Centres
↓
Cloud
↓
GPUs

Those are almost exact inverses.

Oracle sits somewhere else entirely because it arrived carrying:

Databases
+
Enterprise Software
+
Cloud Platform

which neither CoreWeave nor Radiant possessed.

So my assessment would be:

  • CoreWeave and Radiant are the closest opposites.
  • Oracle and Radiant are converging from opposite ends of the technology stack.
  • By 2030, Oracle and Radiant may end up looking surprisingly similar externally, even though one began as a software giant and the other as an infrastructure and energy giant.

Reflective Journeys: Oracle vs Radiant

Yes, in many cases Oracle employees affected by AI-related restructuring could be strong candidates for Radiant, but it depends heavily on which part of Oracle they came from.

The interesting thing is that Oracle and Radiant are moving toward the same destination from opposite directions:

Oracle
Database
↓
Cloud
↓
AI Infrastructure

Radiant
Power
↓
Infrastructure
↓
AI Infrastructure

That creates a surprising amount of skill overlap.

Oracle Employees Radiant Should Recruit Aggressively

OCI Engineers

These are probably the highest-value hires.

Experience:

  • OCI regions
  • Cloud operations
  • Bare metal
  • Networking
  • Cloud automation

Radiant needs people who know how to operate cloud infrastructure at scale.

These engineers bring exactly that.


AI Infrastructure Engineers

Oracle has been building:

  • GPU superclusters
  • RDMA fabrics
  • RoCE networks
  • AI training environments

Those skills are directly transferable to:

  • Radiant AI factories
  • GPU clouds
  • Sovereign AI deployments

OCI SREs

Particularly valuable:

  • Capacity planning
  • Reliability engineering
  • Infrastructure automation
  • Fleet management

Radiant will need these people immediately as AI factories scale.


Data Centre Engineers

Oracle has been building data centres globally.

Skills:

  • Capacity planning
  • Facility operations
  • Power
  • Cooling
  • Commissioning

These map extremely well to Radiant’s infrastructure-first strategy.


Network Engineers

Potentially the most valuable category.

Particularly if they have:

  • RoCE
  • RDMA
  • EVPN/VXLAN
  • High-performance networking

AI infrastructure is increasingly network-limited rather than GPU-limited.


Observability Engineers

This is a category many AI infrastructure companies underestimate.

Skills:

  • OpenTelemetry
  • Prometheus
  • Grafana
  • Logging platforms
  • Distributed tracing

Radiant will eventually need to observe:

Power
Cooling
Networks
Storage
GPUs
Training Jobs
Cloud Platform

at enormous scale.


Oracle Employees Radiant May Need Less Of

Traditional ERP / Applications Teams

Experience in:

  • E-Business Suite
  • HR systems
  • Legacy applications

is less directly relevant.

Radiant is building infrastructure rather than enterprise applications.


Traditional Database Administration

Still useful, but lower priority.

Radiant’s biggest bottlenecks are more likely:

  • GPUs
  • Networking
  • Data centres
  • Cloud platforms

than Oracle Database administration.


Would It Be Good For The Employees?

Potentially yes.

Oracle is becoming:

Large AI Hyperscaler

Radiant is becoming:

AI Infrastructure Startup
with Brookfield backing

Some engineers prefer:

Oracle

  • Stability
  • Massive scale
  • Mature processes
  • Existing customer base

Radiant

  • Building from scratch
  • More influence
  • Faster decision making
  • Potentially larger individual impact

If I Were Radiant’s CTO

The first Oracle hires I would target would be:

  1. OCI Principal SREs
  2. OCI Network Architects
  3. OCI GPU Platform Engineers
  4. OCI Capacity Engineers
  5. OCI Observability Platform Engineers
  6. OCI Data Centre Build Engineers

These people have already operated infrastructure at scales that Radiant wants to achieve.


Looking at Your Background

Based on the areas you’ve worked deeply in—observability, OpenTelemetry, Prometheus/Mimir/Loki/Tempo, Kubernetes, HPC, storage, automation, cloud platforms, and AI infrastructure—the type of role that would likely be most valuable to a company like Radiant is not a generic SRE.

It would be something closer to:

  • Principal Observability Engineer
  • AI Infrastructure Observability Architect
  • Staff SRE (AI Platforms)
  • Platform Engineering Lead
  • AI Factory Telemetry Architect

because one of the hardest problems these emerging AI infrastructure companies will face is creating observability across the entire stack:

Power
↓
Data Centre
↓
Network Fabric
↓
GPU Cluster
↓
Kubernetes / Slurm
↓
AI Workloads

Very few engineers have practical experience spanning that many layers.

One caveat: public reporting has discussed Oracle workforce reductions in various parts of the business, but I have not seen reliable evidence supporting a single confirmed figure of “30,000 layoffs” across Oracle as a whole. When evaluating career moves, it’s better to focus on the strategic trend—Oracle investing heavily in AI infrastructure and cloud—rather than any specific layoff number unless confirmed by Oracle itself.

Where is all the Money?

The short answer is:

The money is real, but most of it is not sitting in a bank account waiting to be spent.

What you’re seeing is a combination of:

  1. Cash flow
  2. Debt financing
  3. Equity financing
  4. Project finance
  5. Infrastructure finance
  6. Customer pre-commitments
  7. Stock market valuations

The AI infrastructure boom is probably the largest capital deployment into technology infrastructure since the construction of the Internet and mobile networks.


Where Does The Money Actually Come From?

Imagine a company announces:

$20 Billion AI Campus

Many people picture:

Bank Account
↓
$20 Billion

That’s almost never what happens.

Instead:

Equity
+
Debt
+
Customer Contracts
+
Infrastructure Loans
+
Future Revenue

fund the project.


CoreWeave

CoreWeave is the easiest example.

They need:

  • GPUs
  • Data centres
  • Power
  • Networking

worth billions.

They fund this through:

Equity

Investors buy shares.

Debt

Banks lend money.

GPU-backed loans

This is fascinating.

CoreWeave can buy:

100,000 H100s

and lenders treat those GPUs almost like collateral.

Similar to:

Mortgage
↔ House

Loan
↔ GPU Fleet

Oracle

Oracle is different.

Oracle generates tens of billions in annual revenue.

Their funding comes primarily from:

Operating Cash Flow

Database Revenue
SaaS Revenue
Support Contracts
OCI Revenue

This is actual cash arriving every quarter.

Oracle can invest from profits.

Corporate Debt

Oracle also issues bonds.

For example:

Oracle Bond
↓
Investors buy it
↓
Oracle receives cash

This is normal corporate finance.


AWS

AWS funding is even simpler.

Amazon generates huge cash flows.

When AWS builds a data centre:

Retail Business
+
AWS Revenue
+
Debt Markets

fund it.

The money is real.


Microsoft

Microsoft is currently spending at extraordinary levels.

Funding comes from:

Windows

Office 365

Azure

LinkedIn

GitHub

Copilot

All producing cash.

Microsoft can spend tens of billions annually because they generate enormous free cash flow.


Nscale

Nscale is much more interesting.

Nscale doesn’t have Oracle’s cash flow.

Instead funding comes from:

Equity Investors

Strategic Investors

Infrastructure Finance

Project Finance

Future Customer Contracts

Think:

Power Agreement
+
Land
+
Customer Demand
↓
Banks lend money

Crusoe

Crusoe is heavily project-finance oriented.

Example:

OpenAI
↓
Needs Capacity

Oracle
↓
Needs Capacity

Crusoe
↓
Build Campus

The campus may be funded by:

  • Equity
  • Infrastructure loans
  • Project financing
  • Long-term customer commitments

Similar to how airports and power stations are financed.


Radiant

Radiant may have the strongest financing model.

Why?

Because Brookfield already finances:

  • Power stations
  • Airports
  • Ports
  • Railways
  • Data centres

worth hundreds of billions.

Brookfield understands:

Build Asset
↓
Generate Revenue
↓
Repay Debt

better than almost anyone.

Radiant can potentially tap into infrastructure capital that many neoclouds cannot.


Is The Money “Real”?

Yes.

But there are three different meanings.


Real Cash

Example:

Microsoft earns:

$100

Customer pays.

Microsoft receives:

$100 cash

Real money.


Debt

Example:

Bank lends:

$10 Billion

to build AI infrastructure.

Also real money.

But must be repaid.


Market Valuation

This is where people get confused.

Example:

CoreWeave market cap:

$56 Billion

That does NOT mean:

$56 Billion cash

exists.

It means:

Share Price × Shares Outstanding

equals $56B.

Much of that value exists “on paper.”


The Hidden Fuel: Pension Funds

Most people don’t realize who ultimately finances much of this.

The money often comes from:

  • Pension funds
  • Sovereign wealth funds
  • Insurance companies
  • Infrastructure funds

For example:

Teacher Pension
↓
Infrastructure Fund
↓
Brookfield
↓
AI Data Centre

The chain can be surprisingly long.


Why Everyone Is Comfortable Lending

The reason banks are willing to lend is simple:

They believe AI demand will continue growing.

Their assumption is:

GPU Demand
>
Debt Cost

If true:

  • Loans get repaid.
  • Investors make money.
  • Infrastructure grows.

If false:

  • Some companies will fail.
  • Some campuses will be underutilized.
  • Some lenders will take losses.

The Biggest Risk

The entire AI infrastructure sector is making a giant bet:

Future AI Demand

If AI demand keeps growing:

  • Oracle wins.
  • Microsoft wins.
  • CoreWeave wins.
  • Crusoe wins.
  • Nscale wins.
  • Radiant wins.

If demand slows dramatically:

The most leveraged companies suffer first.

That is why investors currently view:

CompanyFinancial Risk
MicrosoftLow
OracleLow
AWSLow
GoogleLow
Radiant/BrookfieldModerate
CrusoeModerate
NscaleModerate-High
CoreWeaveHigh

The hyperscalers are largely spending from enormous existing cash flows. The neoclouds are spending mostly against future growth, future contracts, and infrastructure financing. The money is real, but much more of the neocloud funding stack depends on future demand continuing to justify today’s investments.

The 2026 AI Funding Diagram

Key changes since the Bloomberg/Morgan Stanley “AI Money Machine” chart from late 2025

OpenAI

  • Valuation increased from roughly $500B to over $730B–850B after its record funding rounds in 2026.
  • New major funding sources:
    • Amazon
    • SoftBank
    • Nvidia
  • OpenAI is now much less dependent on Microsoft than the original chart suggests.

Amazon (missing from the original)

Amazon is arguably the biggest omission now:

  • Invested approximately $50B in OpenAI.
  • Expanded AWS compute commitments.
  • OpenAI agreed to use AWS infrastructure and Trainium capacity.

SoftBank (missing from the original)

  • Became one of OpenAI’s largest financial backers.
  • Major participant in Stargate-style infrastructure funding.

CoreWeave

  • OpenAI relationship expanded to about $22.4B in AI infrastructure contracts.
  • Now one of OpenAI’s largest compute suppliers.
  • Public company rather than private neocloud startup.

Nvidia

  • Still sits at the center.
  • Added direct investment into OpenAI.
  • Continues investing in CoreWeave while simultaneously selling GPUs to it and buying capacity from it.

Nscale and Nebius

  • The original chart correctly anticipated their importance.
  • They now fit into a larger category of “GPU-native neoclouds” alongside CoreWeave.
  • Their role is increasingly as infrastructure providers for AI model companies rather than model developers themselves.

If Bloomberg redrew it today

The centre would probably look like:

                    Microsoft
|
|
Amazon ----\
\
SoftBank ----> OpenAI <---- Nvidia
/ | \
/ | \
/ | \
Oracle CoreWeave AMD
| |
| |
GPU Clouds (Nebius, Nscale)
|
Mistral / xAI / Figure / Cursor

The biggest differences

2025 Chart2026 Reality
Microsoft dominates OpenAI fundingAmazon + SoftBank now rival Microsoft
CoreWeave is peripheralCoreWeave is a central infrastructure supplier
Amazon absentAmazon is one of the largest players
SoftBank absentSoftBank is one of the largest financiers
OpenAI ≈ $500BOpenAI > $730B valuation
Nscale/Nebius nicheNscale/Nebius increasingly recognized as AI infrastructure providers

For your interests in AI infrastructure, neoclouds, and hyperscalers, a more useful 2026 version would actually be an “AI Infrastructure Ecosystem Map” showing:

  • Nvidia
  • AMD
  • OpenAI
  • Microsoft
  • Amazon
  • Oracle
  • SoftBank
  • CoreWeave
  • Nebius
  • Nscale
  • Crusoe
  • xAI
  • Mistral
  • Figure AI
  • Stargate

with arrows for:

  • Capital investment
  • GPU purchases
  • Cloud contracts
  • Equity stakes
  • AI model consumption

That would better reflect where the industry sits today than the original Bloomberg graphic.